Skip to content
Software – REIBuys
  • Home
    • More Apps
      • NORA Desktop App
        • NORA Documentation
        • NORA (EULA)
      • HF AI Video Studio
        • HF AI Video Studio Documentation
    • Blog
    • Support

Best Ollama Models for Coding + How to Use Ollama

June 28, 2026June 25, 2026 by reibuys_software

Best Ollama models for coding, ranked. Install Ollama on Linux, Windows, or Mac and run your first local model in minutes — with a comparison table and quick-start commands.

Categories local-llm-tools Tags coding-models, developer-tools, local-llm, ollama, ollama-setup Leave a comment

How to Run Gemma Locally for Development Workflows

June 28, 2026June 25, 2026 by reibuys_software

Run Gemma locally using Ollama or llama.cpp — step-by-step setup, workflow integration, and a Gemma vs CodeLlama coding comparison to help you choose the right model.

Categories local-llm-setup Tags gemma, gemma-vs-codellama, local-llm, ollama, run-gemma-locally Leave a comment

How Much VRAM & Hardware You Need for Local LLMs

June 28, 2026June 25, 2026 by reibuys_software

Not sure if your hardware can run a local LLM? This guide covers VRAM requirements by model, RAM minimums, GPU tiers, and how to run without a dedicated GPU.

Categories local-llm-hardware Tags gpu-for-llm, llm-setup, local-llm-hardware, run-without-gpu, vram-requirements Leave a comment

Gemma vs CodeLlama: Which Is Better for Coding?

June 28, 2026June 25, 2026 by reibuys_software

Gemma vs CodeLlama for coding: compare coding quality, VRAM, speed, and license side by side. Includes a decision matrix to help you pick the right model for your workflow.

Categories model-comparisons Tags codellama, coding-models, gemma, local-llm, model-comparison Leave a comment

Can You Run a Local LLM Without a GPU? Yes — Here’s How

June 28, 2026June 25, 2026 by reibuys_software

Yes — you can run a local LLM without a GPU. Covers CPU-only inference, best quantised models (GGUF/Q4), and step-by-step setup with llama.cpp and Ollama in CPU mode.

Categories local-llm-hardware Tags cpu-inference, gguf-models, llama-cpp, ollama, run-without-gpu Leave a comment

Best Local LLM for Coding: Top Models Ranked 2026

June 28, 2026June 25, 2026 by reibuys_software

The best local LLMs for coding, ranked by coding strength, VRAM, and speed. Compare CodeLlama, Gemma & Mistral and choose the right model for your setup.

Categories local-llm-coding Tags codellama, coding-models, gemma, local-llm, open-source-llm Leave a comment

Why AI Agents Fail in Production: A Developer’s Perspective

September 4, 2026June 25, 2026 by reibuys_software
Chart illustrating common production AI agent failures such as logical drifts, incorrect API calls, misinterpretation of JSON, infinite loops, and token exhaustion.

When an agent fails locally, you can usually see it instantly in your terminal output. In production, failures are often silent, expensive, and unpredictable. The non-deterministic nature of LLMs mean

Categories ai-agents Tags agent-problems, debugging, production-failures Leave a comment

How to Run Local LLMs with Ollama for Developers

September 4, 2026June 25, 2026 by reibuys_software
A terminal window showing the successful installation of Ollama, indicating the setup guide is complete.

Ollama has revolutionized local inference by abstracting away the complex Python environments and CUDA driver nightmare that traditionally plagued local AI setup.
Categories local-llms Tags automation, local-llms, ollama, setup-guide Leave a comment

Building Internal Automation Tools with Local LLMs

September 4, 2026June 25, 2026 by reibuys_software
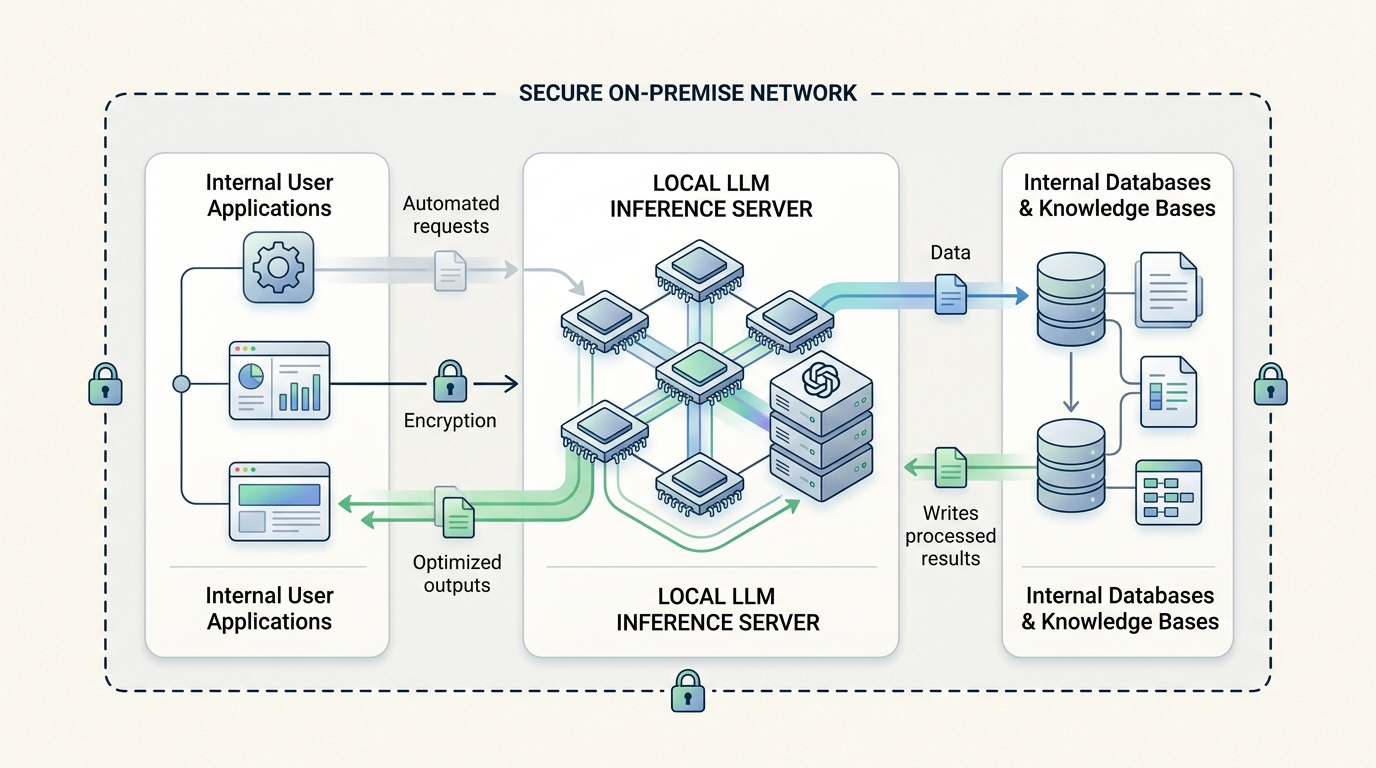
Architecture diagram showing internal applications interacting with a local LLM inference server within a secure network for data privacy and on-premise automation.

For years, developers have defaulted to cloud-based APIs for AI features. However, when building tooling meant exclusively for internal use—such as log analyzers, internal documentation assistants, or
Categories local-llms Tags automation, internal-tools, self-hosted-llm Leave a comment

AI Agent Memory Systems: How to Manage State for LLMs

September 4, 2026June 25, 2026 by reibuys_software
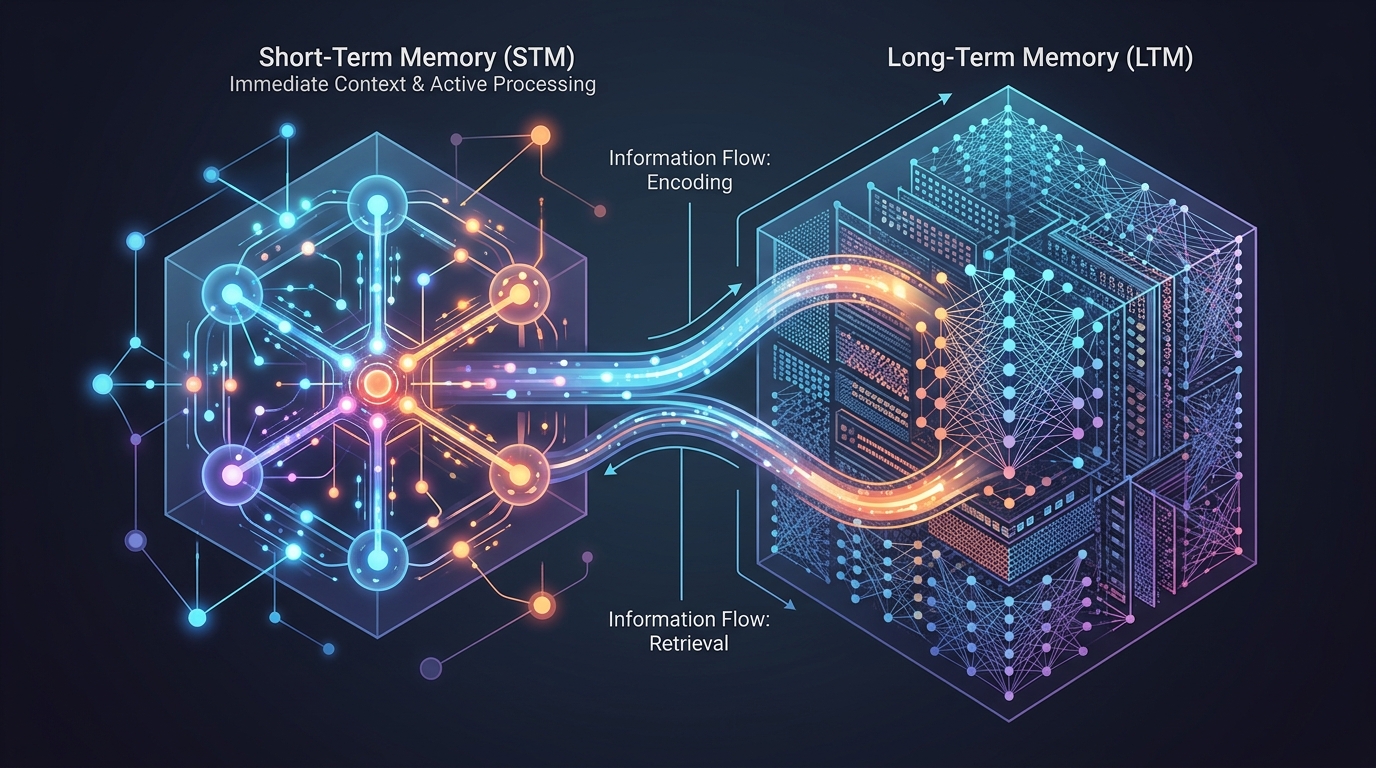
Diagram illustrating the interaction and flow between short-term and long-term memory components within an AI agent's architecture.

[IMAGE: Diagram showing short term vs long term agent memory flow]

Categories ai-agents Tags ai-agent-memory, developers, state-management, vector-memory Leave a comment
Older posts
Newer posts
← Previous Page1 … Page27 Page28 Page29 … Page35 Next →

NORA Documentation

  • NORA Documentation
    • Getting Started with NORA
    • Interface Overview
    • Node Types
    • Building Workflows
    • Running Workflows
    • AI Features
    • Tool Library
    • Settings & Configuration
    • Reference
    • Let’s Get Started Workflow
    • Google Drive Collaboration

HF AI Video Studio Docs

  • HF AI Video Studio Documentation
    • 01 — Introduction
    • 02 — Getting Started
    • 03 — Interface Overview
    • 04 — Video Editing
    • 05 — Audio Editing
    • 06 — Voice Studio
    • 07 — Animated Captions
    • 08 — AI Image Generation
    • 09 — AI Video Generation
    • 10 — Talking Head / Lip-Sync Video
    • 11 — AI Audio & Music Generation
    • 12 — Long-Form Video Pipeline
    • 13 — Job Queue
    • 14 — Settings Reference
    • 15 — Exporting
    • 16 — Common Workflows
    • 17 — Troubleshooting & FAQ

Recent Posts

  • Top Open Source LLM Platforms and Self-Hosted Tools
  • Local LLM Software Comparison: Finding the Right AI Tool
  • The Ultimate Guide to Local LLM Model Formats
  • The Best Local LLM Format to Download in 2026
  • How to Troubleshoot Slow Ollama Setups on Mac and Windows
© 2026 Software - REIBuys • Built with GeneratePress