
Local LLM vs ChatGPT Accuracy: Comparing Quality and Performance
As open-source artificial intelligence models advance at an unprecedented pace, developers, privacy advocates, and IT teams are asking a crucial question: how does local LLM vs ChatGPT accuracy compare in real-world applications?
Running a local model on your own hardware provides absolute privacy, zero latency delays, offline autonomy, and freedom from recurring subscription costs. However, privacy and cost advantages mean little if response quality falls flat. When users test open-source models against commercial powerhouses like OpenAI’s GPT-4, they often notice stark differences in reasoning, precision, and instruction following.
In this comprehensive evaluation, we compare local LLM vs cloud LLM quality, unpack why commercial APIs maintain an edge, and identify exact scenarios where self-hosted models are not only “good enough,” but superior.
Understanding the Accuracy Gap Between Local and Cloud LLMs
To evaluate local AI fairly, we must define what “accuracy” means in language modeling. Accuracy is not merely reciting factual trivia; it encompasses logical coherence, mathematical deduction, precise instruction compliance, contextual memory retention, and low hallucination rates.
A visual comparison of accuracy between local LLMs and cloud-based models like ChatGPT in complex reasoning tasks.
When comparing a consumer-grade 8B or 70B local model to cloud-hosted flagships, an accuracy gap exists across several key dimensions:
- Instruction Following: Cloud models strictly adhere to multi-step constraints (e.g., “Format output as JSON, exclude preamble, and limit response to 100 words”). Smaller local models frequently slip up on negative constraints or format restrictions.
- Contextual Synthesis: In lengthy documents, local models often struggle with the “needle in a haystack” problem—failing to recall small details embedded deep within a long context window.
- Hallucination Rate: Smaller parameter sizes limit factual density. As a result, local models fabricate facts or citations more often when pushed outside their core training data.
However, this quality gap is not uniform across all tasks. Depending on your workload, the real-world gap between local LLM vs GPT-4 may range from substantial to completely negligible.
Local LLM vs ChatGPT Accuracy Breakdown
To understand practical differences, let us examine three core benchmarks: reasoning, programming, and creative writing.
Reasoning and Logic Tasks
Multi-step logical reasoning is where cloud-based LLMs demonstrate their biggest advantage.
- Cloud Models (ChatGPT / GPT-4): Advanced cloud models use massive parameter depth to break complex problems into sequential reasoning steps. They excel at multi-variable logic puzzles, complex financial analysis, and legal document interpretation.
- Local LLMs (7B – 70B): A 70B parameter open-source model (such as Llama 3 70B or Qwen 2.5 70B) achieves remarkable reasoning capability, often approaching GPT-4 benchmarks. (Llama 3 70B) However, lightweight 7B and 8B models suffer noticeable performance drop-offs when handling intricate logic problems that require sustained abstraction.
Coding and Technical Assistance
For software development, code completion, and syntax generation, local models have closed the gap remarkably fast.
- Cloud Models: ChatGPT provides reliable code refactoring across multi-file codebases, excels at debugging esoteric runtime errors, and understands complex architectural frameworks effortlessly.
- Local LLMs: Specialized coding models (such as DeepSeek-Coder or Qwen-Coder) running locally deliver exceptional performance for function writing, boilerplate generation, unit test creation, and API scripting. On standardized coding benchmarks like HumanEval, leading local code models perform on par with—or even outpace—standard GPT-3.5 and early GPT-4 checkpoints.
Creative Writing and Tone Matching
In subjective domains like creative writing, tone adjustment, and brainstorming, raw benchmark numbers matter far less than stylistic preference.
- Cloud Models: Commercial APIs enforce heavy safety RLHF (Reinforcement Learning from Human Feedback), which can sometimes yield overly formal, defensive, or sanitized responses.
- Local LLMs: Uncensored or fine-tuned open-source models offer vastly superior flexibility for roleplay, creative fiction, narrative style matching, and niche branding copy, making them highly desirable for creative workflows.
Why Does GPT-4 Outperform Local Models?
The superior accuracy of top-tier cloud models boils down to two core technical advantages: training scale and hardware architecture.
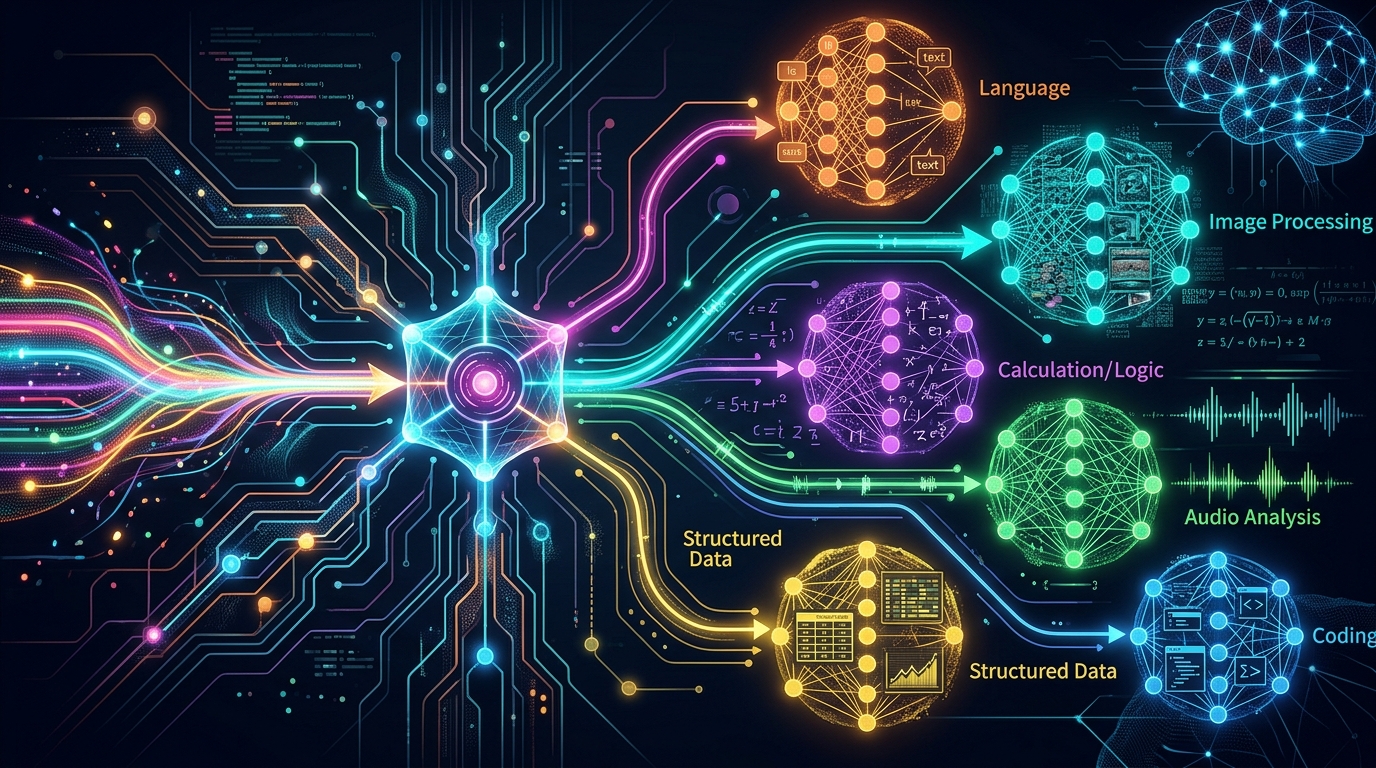
The Mixture of Experts (MoE) architecture allows cloud AI models to leverage multiple specialized networks for different tasks, enhancing performance.
Training Data Volume and RLHF
Commercial AI companies invest heavily in dataset curation, synthetic data generation, and extensive human alignment:
- Trillions of Tokens: Proprietary cloud models are trained on curated datasets spanning tens of trillions of tokens, including licensed proprietary databases.
- Extensive RLHF: Commercial models undergo thousands of hours of Reinforcement Learning from Human Feedback and Direct Preference Optimization (DPO), teaching the model precisely how humans expect answers formatted and refined.
MoE (Mixture of Experts) Architecture
Rather than running a single monolithic network, top cloud systems utilize Mixture of Experts (MoE) architecture. (Mixture of Experts (MoE))
An MoE model consists of multiple specialized sub-networks (“experts”). When a query arrives, a routing mechanism directs the request to the specific experts best suited for that task. This structure grants the model hundreds of billions (or trillions) of total parameters while keeping inference compute manageable. Consumer hardware lacks the VRAM required to load these massive MoE weight files locally without extreme memory quantization.
When Is Local LLM Quality “Good Enough”?
While GPT-4 wins on frontier benchmarks, cloud supremacy is often overkill for daily productivity. A local model is more than “good enough” in the following scenarios:
- Strict Data Privacy Requirements: When processing sensitive legal contracts, medical records, proprietary codebases, or confidential financial records, sending data to external cloud APIs poses compliance risks. A local LLM guarantees 100% data privacy.
- Structured Text Processing: Tasks like summarization, entity extraction, grammar correction, and text reformatting do not require GPT-4 level intelligence. An 8B local model executes these tasks with high accuracy.
- Low-Latency Autocomplete: When integrated into code editors for real-time line completions, locally hosted models eliminate network latency, providing instant feedback.
- Offline or Air-Gapped Operations: In remote locations, field ops, or secure network environments without internet access, local LLMs provide full capability without external dependencies.
How to Bridge the Gap Between Local LLMs and Cloud AI
If you rely on local AI but need higher accuracy, you do not have to accept sub-par outputs. You can actively close the performance gap using targeted strategies:
- Implement Structured Prompting: Smaller models need clear structure. Use system prompts, explicit output formats, and few-shot examples to boost response consistency.
- Employ Retrieval-Augmented Generation (RAG): Connect your local model to a vector database containing your personal files. RAG supplies exact factual context, virtually eliminating factual hallucinations.
- Optimize Parameter Settings: Fine-tuning temperature and top-K sampling can dramatically enhance your local LLM’s accuracy for logic-heavy tasks.
- Select Purpose-Built Models: Avoid relying on a single generalist model. Work on selecting the most accurate local models tailored to your specific workflow—such as using dedicated code models for programming and instruct-tuned models for analysis.
FAQs: Local vs Cloud LLM Performance
Can a local LLM ever beat GPT-4 in accuracy?
In domain-specific tasks, yes. A smaller 14B or 70B local model fine-tuned on specialized domain data (e.g., proprietary legal codes or internal corporate documentation) will frequently outperform a generalized model like GPT-4 on those specific tasks.
What size local model is needed to rival ChatGPT?
For general conversational quality matching standard ChatGPT (GPT-3.5 tier), a modern 8B parameter model (such as Llama 3.1 8B or Qwen 2.5 7B) is sufficient. To approach GPT-4 level logic and complex reasoning, you generally need a 70B parameter model or an advanced MoE model like Mixtral 8x22B.
Why do local models hallucinate more than cloud AI?
Local models typically have smaller parameter counts, meaning they store less parametric knowledge within their weights. When asked about niche topics, smaller models lack the deep memory storage to retrieve exact facts, leading to higher hallucination rates.
Is running a local LLM cheaper than paying for ChatGPT Plus?
If you already own hardware with a capable GPU (such as an Nvidia RTX 3090/4090 or Apple Silicon Mac with 32GB+ unified memory), running local LLMs is virtually free after accounting for electricity. (Nvidia RTX 4090) However, purchasing hardware solely to run massive 70B models can take years to offset a $20/month cloud subscription.