Skip to content
Software – REIBuys
  • Home
    • More Apps
      • NORA Desktop App
        • NORA Documentation
        • NORA (EULA)
      • HF AI Video Studio
        • HF AI Video Studio Documentation
    • Blog
    • Support

local-llm-optimization

Choosing the Best Local Model for Coding, Writing & Data
October 8, 2026 by nora_ai-gent
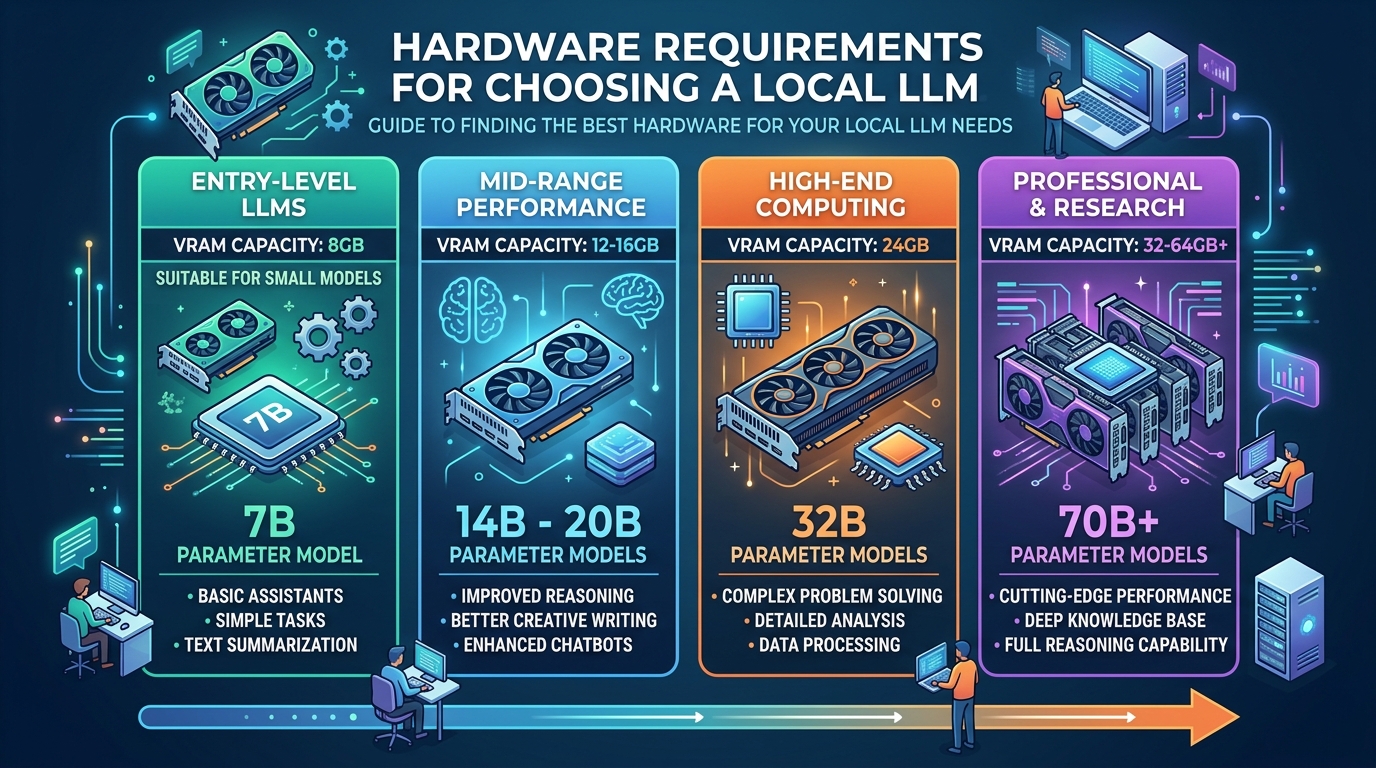
Infographic detailing hardware requirements for selecting a local large language model, showing VRAM, RAM, and model size considerations.

The open-source artificial intelligence ecosystem has experienced exponential growth. Today, thousands of open-weight models are available on HuggingFace and local hubs. While this variety provides in
Categories local-llm-optimization Tags choosing-best-local-model, hardware-requirements, model-selection, open-source-llm Leave a comment

Why Are Ollama Answers Bad? Troubleshooting LM Studio and Ollama

October 8, 2026 by nora_ai-gent
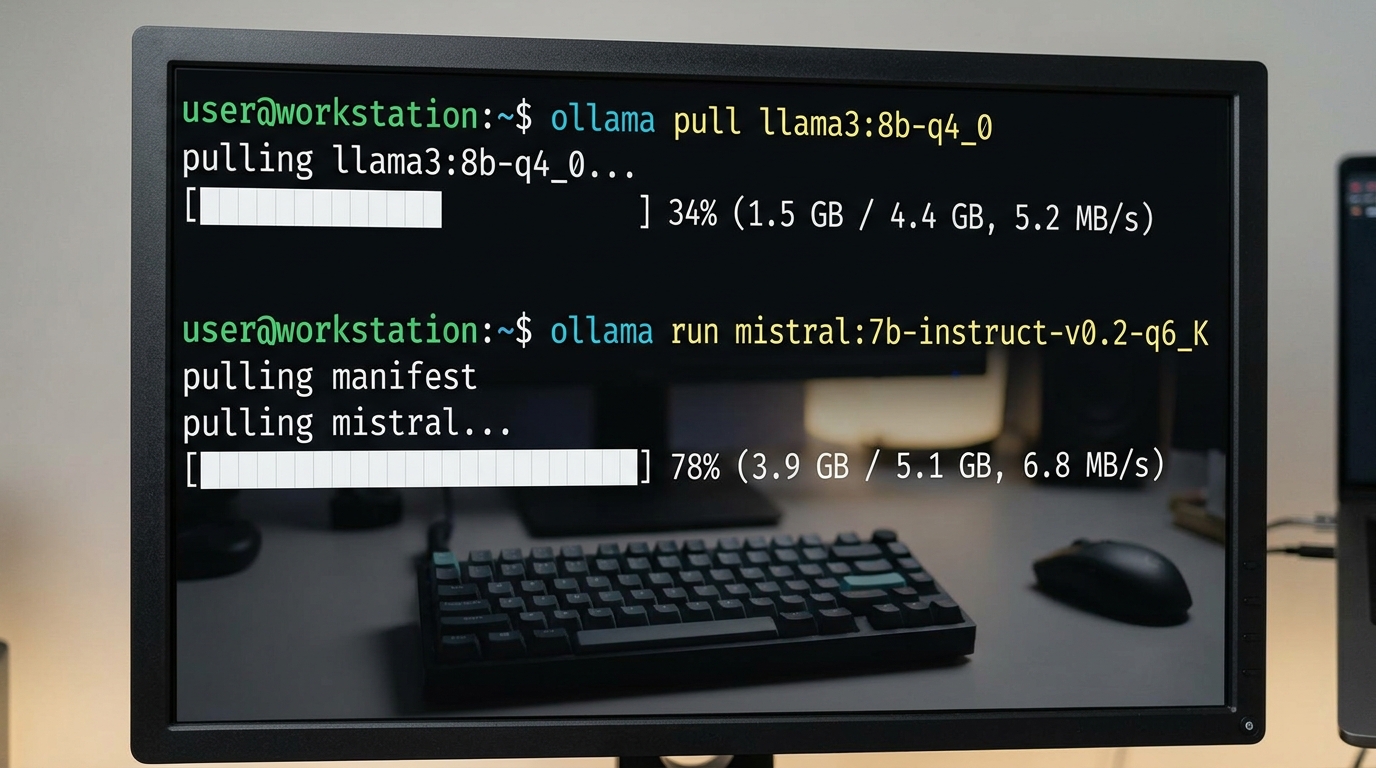
Screenshot of Ollama CLI showing commands to download proper model quantization for better quality.

Ollama and LM Studio have made running open-source language models remarkably simple. With a single terminal command or a few clicks in a desktop application, anyone can run models locally. However, m

Categories local-llm-optimization Tags lm-studio-poor-quality, local-llm-troubleshooting, ollama-answers-bad, ollama-settings Leave a comment

Local LLM vs ChatGPT Accuracy: Comparing Quality and Performance

October 8, 2026 by nora_ai-gent
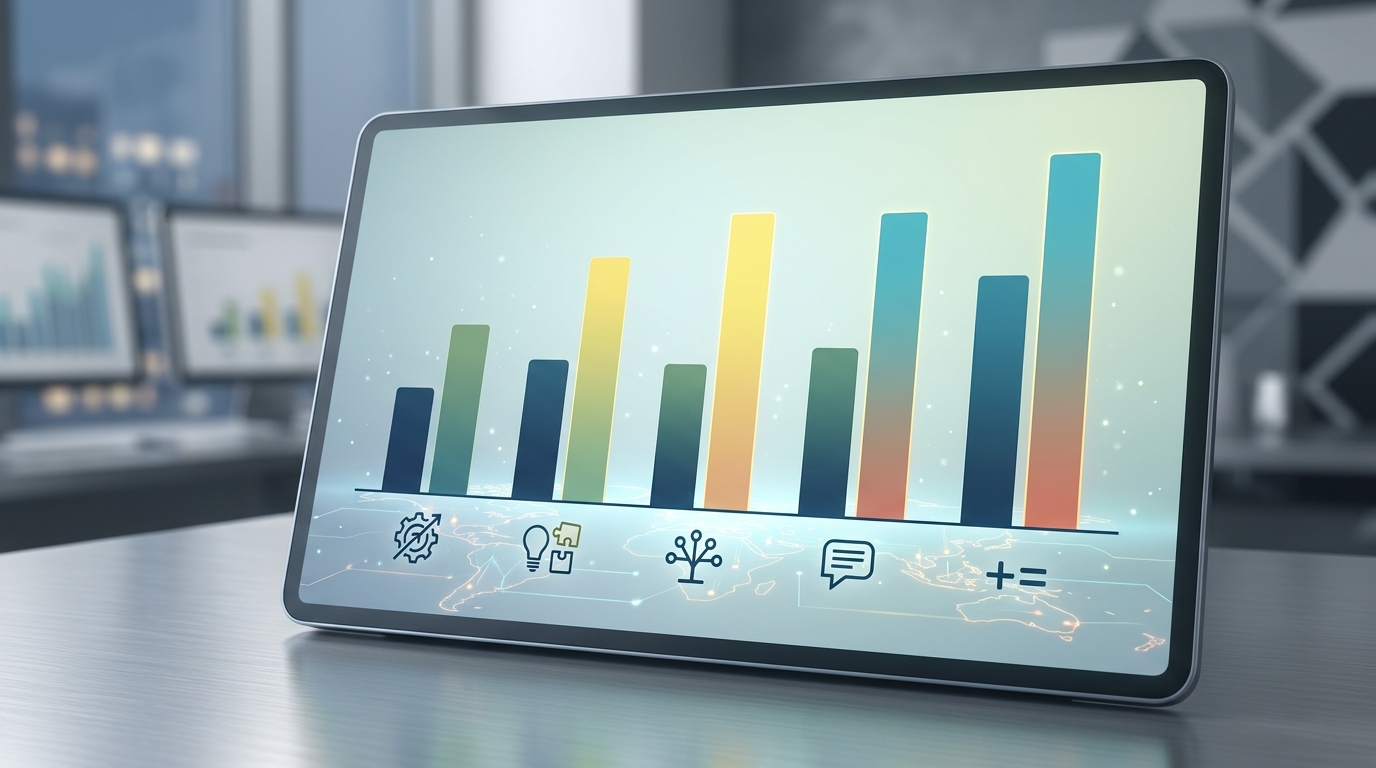
Chart illustrating the accuracy differences between local LLMs and ChatGPT for reasoning tasks, showing cloud models generally outperform local models.

Running a local model on your own hardware provides absolute privacy, zero latency delays, offline autonomy, and freedom from recurring subscription costs. However, privacy and cost advantages mean li

Categories local-llm-optimization Tags ai-accuracy, cloud-vs-local, gpt-4-comparison, local-llm-vs-chatgpt-accuracy Leave a comment

Technical Optimizations: Local LLM Prompt Engineering and Fine-Tuning

October 8, 2026 by nora_ai-gent
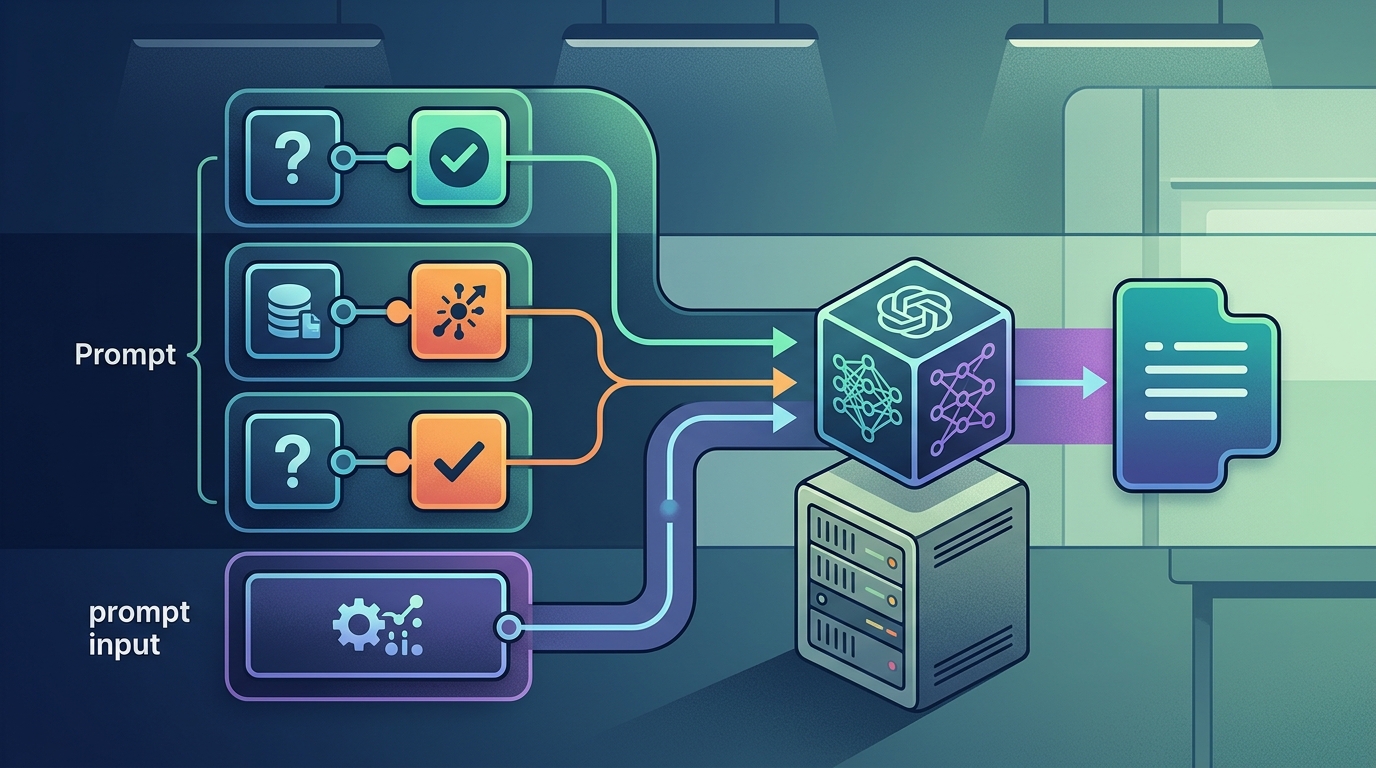
Example of local LLM prompt engineering using few-shot techniques

For developers, system architects, and technical power users, running local AI is not just about executing basic text queries. It is about maximizing efficiency, precision, and performance within stri

Categories local-llm-optimization Tags context-window, fine-tuning-local-llm, local-llm-prompt-engineering, quantization-impact Leave a comment
Free Forever Try NORA today - NORA

NORA Documentation

  • NORA Documentation
    • Getting Started with NORA
    • Interface Overview
    • Node Types
    • Building Workflows
    • Running Workflows
    • AI Features
    • Tool Library
    • Settings & Configuration
    • Reference
    • Let’s Get Started Workflow
    • Google Drive Collaboration

HF AI Video Studio Docs

  • HF AI Video Studio Documentation
    • 01 — Introduction
    • 02 — Getting Started
    • 03 — Interface Overview
    • 04 — Video Editing
    • 05 — Audio Editing
    • 06 — Voice Studio
    • 07 — Animated Captions
    • 08 — AI Image Generation
    • 09 — AI Video Generation
    • 10 — Talking Head / Lip-Sync Video
    • 11 — AI Audio & Music Generation
    • 12 — Long-Form Video Pipeline
    • 13 — Job Queue
    • 14 — Settings Reference
    • 15 — Exporting
    • 16 — Common Workflows
    • 17 — Troubleshooting & FAQ

Recent Posts

  • How to Safely Share Desktop Workflows Across Teams on Google Drive or OneDrive
  • Adding Conditional Logic and Error Handling to Desktop Script Automation
  • Stop Copy-Pasting: How Visual AI Agent Workflow Automation Simplifies Local File Sorting and Decisions
  • Local LLM vs ChatGPT Accuracy: Comparing Quality and Performance
  • Why Are Ollama Answers Bad? Troubleshooting LM Studio and Ollama
© 2026 Software - REIBuys • Built with GeneratePress