
The Best Local LLMs You Can Run on a 16GB RAM Laptop
Running artificial intelligence locally on personal hardware has evolved from an experimental curiosity into an essential workflow for developers, researchers, and privacy-conscious users. However, one common constraint modern creators encounter is system memory. If you own a laptop or desktop equipped with 16GB of system memory, you might wonder whether your hardware can effectively handle modern open-weight language models without suffering severe slowdowns or out-of-memory errors.
The short answer is yes—16GB of RAM is a practical sweet spot for running high-quality small language models. Thanks to advancements in quantization techniques, architectural optimizations, and inference engines, choosing the best local LLM 16gb ram setups can deliver responsive coding assistance, text summarization, and interactive chat directly on your machine.
In this comprehensive guide, we examine the minimum requirements for running open models locally, evaluate the top small models available in 2026, and explore how to pick the right architecture for your hardware.
Modern laptops with 16GB of RAM are increasingly capable of running powerful local LLMs for various tasks.
What LLM Can I Run with 16GB of RAM?
When selecting a low resource llm laptop candidate, understanding model sizing is crucial. Open-weight models are defined primarily by parameter count—such as 3B (3 billion), 7B/8B, 14B, or 70B parameters—and their precision format (FP16, Q8, Q4, Q2, etc.).
On a machine with 16GB of total system RAM, your system operating system (macOS, Windows, or Linux) and background applications typically consume anywhere from 3GB to 6GB of RAM. This leaves approximately 10GB to 13GB of available memory dedicated to loading the model weight tensors and maintaining the key-value (KV) context cache during inference.
As a general rule:
* 3B to 4B Parameter Models: Fit completely in memory with minimal footprint (requiring ~2GB to 4GB RAM), allowing massive context windows and fast token generation even on modest hardware.
* 7B to 9B Parameter Models: Fit comfortably when quantized to 4-bit (Q4_K_M) or 5-bit (Q5_K_M) formats, taking up ~5GB to 7GB of RAM. This represents the optimal balance between reasoning accuracy and execution speed on 16GB laptops.
* 14B Parameter Models: Can run in heavily quantized formats (such as 3-bit or 4-bit), consuming ~8GB to 10GB of RAM, but leave less headroom for large context windows or multitasking.
Local LLM Minimum Requirements (16GB RAM Explained)
To understand why 16GB RAM works well for modern local AI, consider the memory breakdown required for smooth local inference:
| Component | RAM Consumption | Notes |
|---|---|---|
| Operating System & Overhead | 3.0 GB – 5.0 GB | Windows 11 / macOS ambient usage |
| Model Weights (7B / 8B Q4) | 4.5 GB – 5.5 GB | Loaded into system RAM or VRAM |
| Context Window Cache (8K tokens) | 1.0 GB – 2.0 GB | Varies based on context length & precision |
| Available Buffer | 3.5 GB – 5.5 GB | Keeps system stable without swapping |
If you are evaluating local llm minimum requirements 16gb systems, keep in mind that hardware acceleration plays a major role. Laptops with unified memory architectures—such as Apple Silicon MacBooks—allow the GPU to directly access system memory without duplicating model weights. For Windows machines with discrete GPUs (such as an NVIDIA RTX GPU with 6GB or 8GB VRAM), offloading a portion of the layers to GPU VRAM while leaving the rest in system RAM allows flexible hybrid execution.
If you are using Apple hardware, you can follow our step-by-step guide to run a local LLM on Mac without ML experience to configure your environment in minutes.
Top 5 Best Small LLMs for 16GB RAM
Finding the best llm for 16gb laptop configurations means targeting models under 10 billion parameters that offer strong instruction-following, logical reasoning, and coding capabilities while maintaining swift generation speeds (tokens per second). Here are the top 5 small models optimized for 16GB hardware in 2026:
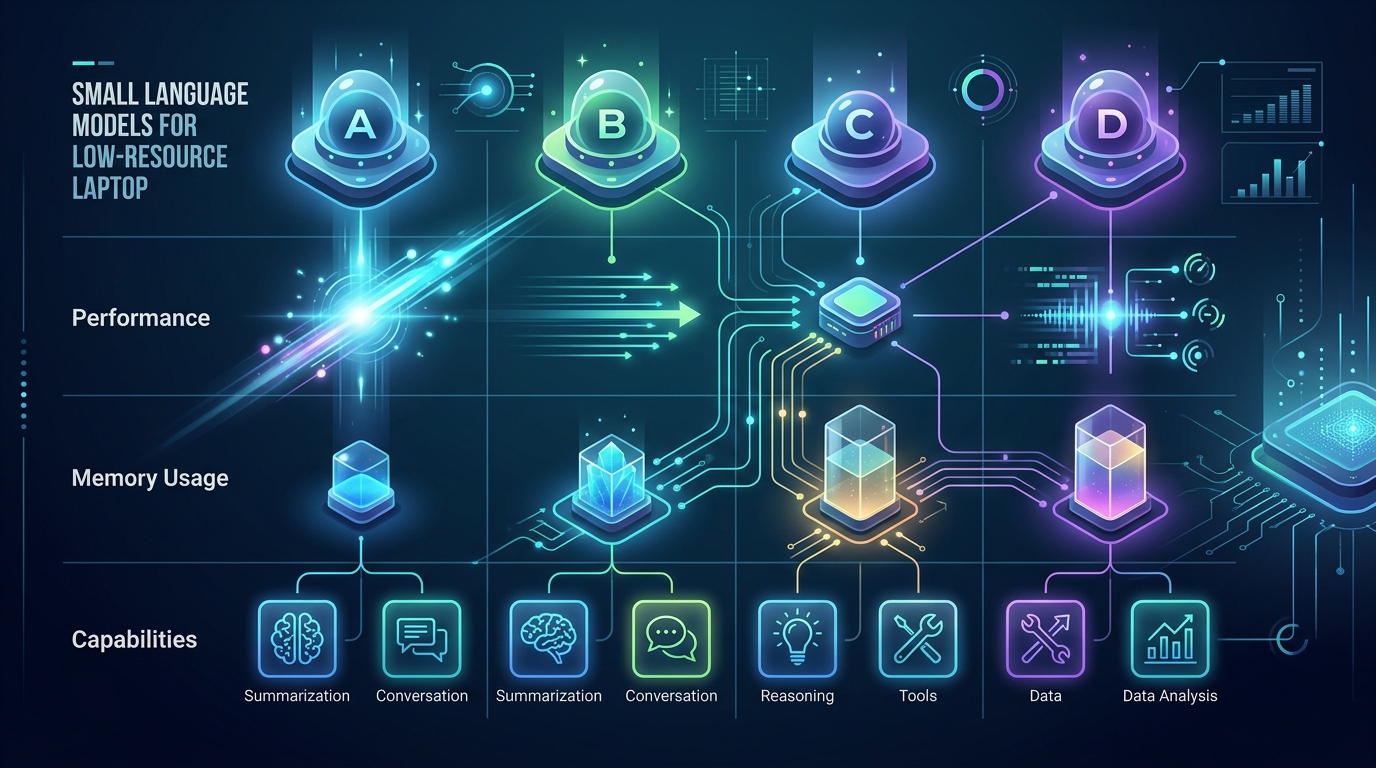
Comparing the top small LLMs reveals a balance between performance, memory footprint, and specialized capabilities for 16GB RAM laptops.
1. Llama 3.1 8B (Best Local Model Overall)
Meta’s Llama 3.1 8B remains the benchmark standard for open-weight best small llm 16gb deployment. (Llama 3.1 8B) Quantized to 4-bit (Q4_K_M GGUF), the model requires roughly 4.9 GB of memory, making it remarkably easy to run alongside your code editor or browser.
* Best For: General conversational AI, text synthesis, structured output generation, and coding support.
* RAM Required (Q4_K_M): ~5.1 GB total footprint.
* Key Strength: Exceptional multi-turn conversation ability and strong tool-use alignment.
2. Mistral 7B Instruct v0.3 (Best Low Resource LLM for Laptops)
Mistral AI’s 7B parameter architecture was a pioneer in high-density reasoning for small footprint models. Mistral 7B Instruct v0.3 offers an enlarged context window, fast decoding speeds, and efficient memory usage. (Mistral 7B Instruct v0.3)
* Best For: Fast retrieval-augmented generation (RAG), quick summaries, and low-latency local queries.
* RAM Required (Q4_K_M): ~4.4 GB.
* Key Strength: High token throughput on CPU-only or integrated graphics setups.
3. Gemma 2 9B (Best for Complex Reasoning)
Google’s Gemma 2 9B utilizes an advanced architecture with alternating local and global attention layers, delivering intelligence scores that frequently challenge larger 13B and 14B models. (Gemma 2 9B)
* Best For: Analytical problem solving, mathematical reasoning, and complex document analysis.
* RAM Required (Q4_K_M): ~5.8 GB.
* Key Strength: Outperforms many larger models on logical benchmarks while maintaining a compact footprint.
4. Phi-3.5 Mini 3.8B (Best Ultra-Lightweight Model)
Microsoft’s Phi-3.5 Mini demonstrates that parameter efficiency can achieve remarkable results. At under 4 billion parameters, it offers reasoning capabilities that rival older 7B models while occupying minimal RAM.
* Best For: Ultra-fast responses, background agent tasks, and laptops running strictly on battery power.
* RAM Required (Q4_K_M): ~2.3 GB.
* Key Strength: extremely fast inference speed and negligible RAM usage, leaving over 10GB free for heavy background applications.
5. Qwen 2.5 7B / Coder 7B (Best for Software Engineering)
Alibaba’s Qwen 2.5 7B series (specifically Qwen 2.5 Coder 7B) provides specialized programming expertise directly on your machine. (Qwen 2.5 7B / Coder 7B)
* Best For: Local code completion, debugging, refactoring, and technical documentation.
* RAM Required (Q4_K_M): ~4.7 GB.
* Key Strength: Matches or exceeds cloud coding assistants on Python, JavaScript, and Rust generation tasks.
For detailed walkthroughs on launching these models using local inference engines, check out our comparative article to compare Ollama vs LM Studio vs Jan AI.
How to Choose the Best LLM for a 16GB Laptop
Selecting the best local model 16gb setup requires evaluating your specific use case against hardware constraints.
Balancing Speed vs. Intelligence
When running AI locally, there is an inherent trade-off between model intelligence (parameter size and quantization accuracy) and generation speed (tokens per second):
1. Higher Precision (Q8 or FP16): Provides marginally better precision and fewer reasoning errors, but consumes twice as much memory and reduces token generation speed on CPU/RAM setups.
2. Standard Quantization (Q4_K_M): The community gold standard. Provides negligible accuracy drop compared to FP16 while drastically reducing memory requirements by 60–70%.
3. Extreme Quantization (Q2_K / IQ3_XS): Allows you to squeeze larger models (like 14B parameter models) into 16GB RAM, but can lead to noticeable degradation in logic and generation stability.
For most laptop llm recommendations, adopting Q4_K_M or Q5_K_M 7B/8B models delivers the ideal balance of fast response times and high-quality outputs.
Hardware Constraints (CPU vs. GPU)
Your hardware architecture dictates how your model will execute:
* Apple Silicon (M1/M2/M3/M4 with 16GB Unified Memory): The unified memory bandwidth (ranging from 100 GB/s to 150 GB/s on base chips) allows local LLMs to generate text quickly (20–40 tokens/sec) directly via Metal GPU acceleration.
* Windows Laptops with Discrete GPU: If your laptop has a GPU with 6GB or 8GB VRAM, offload as many model layers as possible to VRAM using GGUF engine loaders.
* Windows/Linux Laptops with CPU & System RAM: If running CPU-only, memory speed (DDR4 vs DDR5) is your main bottleneck. DDR5 systems yield noticeably faster token generation.
To review complete hardware setup workflows across operating systems, consult our guide on setup instructions to run an LLM on 16GB RAM.
Frequently Asked Questions
What are the minimum requirements for a local LLM?
The baseline minimum hardware requirement to run modern open-weight LLMs is a 64-bit x86 or ARM processor (such as Intel Core i5/i7/i9, AMD Ryzen 5/7/9, or Apple Silicon), 8GB of system RAM for 3B models, or 16GB of system RAM for 7B/8B 4-bit quantized models. Solid-State Storage (SSD) is strongly recommended to ensure fast model loading times.
Is 16GB RAM enough for Llama 3?
Yes, 16GB of RAM is fully sufficient to run Llama 3 and Llama 3.1 8B in 4-bit (Q4_K_M) or 5-bit (Q5_K_M) quantized GGUF formats. A 4-bit quantized Llama 3.1 8B model requires approximately 5.1GB of RAM, leaving ample overhead on a 16GB system for your operating system, context buffer, and other software applications.
To discover specific model variants and download tags tuned for command-line inference, explore specific Ollama 16GB RAM models in our dedicated breakdown.