Skip to content
Software – REIBuys
  • Home
    • More Apps
      • NORA Desktop App
        • NORA Documentation
        • NORA (EULA)
      • HF AI Video Studio
        • HF AI Video Studio Documentation
    • Blog
    • Support

ai-coding-tools

How to Fix an Ollama Model That Is Not Responding
October 8, 2026 by nora_ai-gent
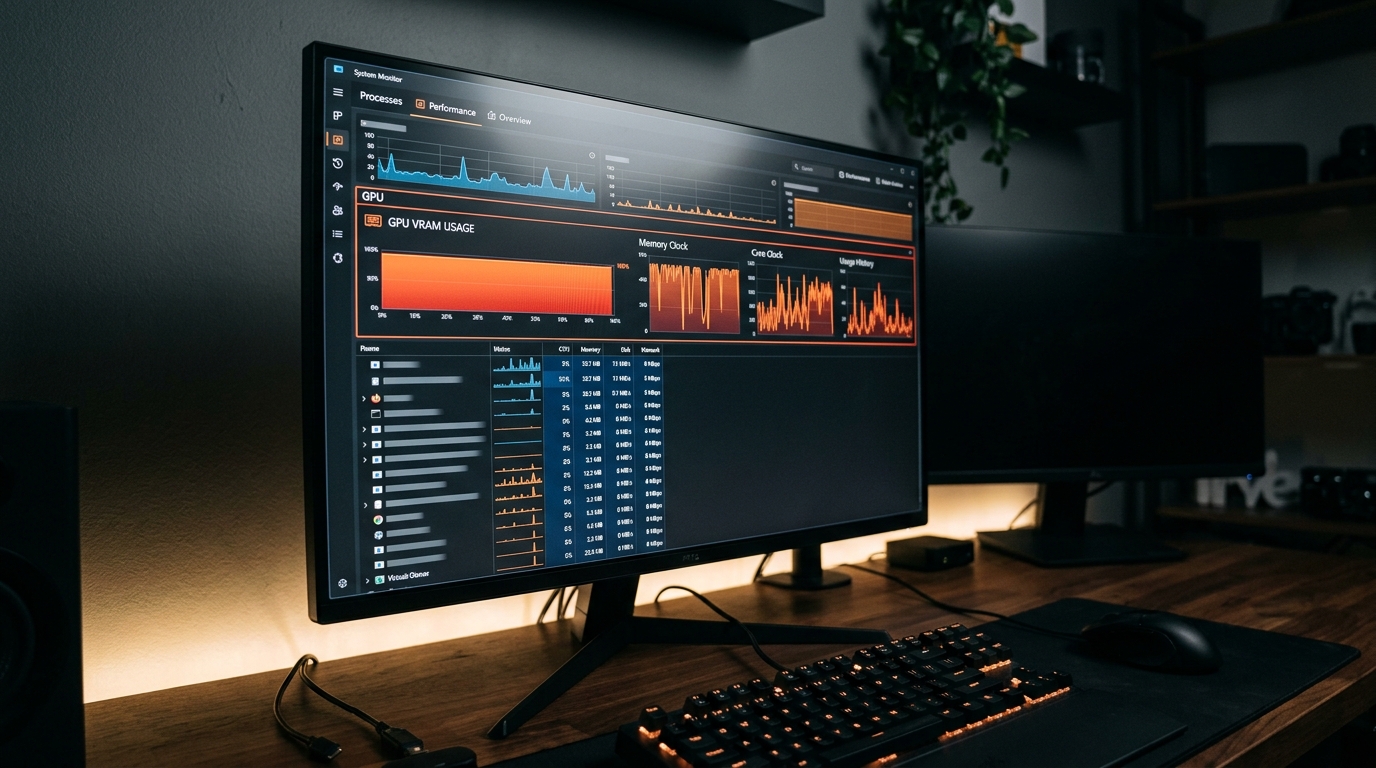
A system monitoring tool displaying high GPU VRAM usage, indicating a potential memory issue preventing an Ollama model from responding.

Ollama relies on accelerated computing libraries like NVIDIA CUDA, AMD ROCm, or Apple Metal to run models efficiently. If Ollama cannot access hardware acceleration properly, execution degrades or han
Categories ai-coding-tools Tags local-llm, ollama-fix, ollama-troubleshooting, vram-errors Leave a comment

How to Implement LangChain Local LLM Memory in Python

October 8, 2026 by nora_ai-gent
Abstract representation of LangChain managing memory for local LLMs, showing data flow and context.

When building local AI applications, conversational agents, or developer tools in Python, managing message history manually using raw lists quickly becomes tedious. As multi-turn dialogue grows, devel

Categories ai-coding-tools Tags langchain, llm-memory, local-llm, ollama, python Leave a comment

Managing Ollama Chat History & Making LM Studio Remember Chat

October 8, 2026 by nora_ai-gent
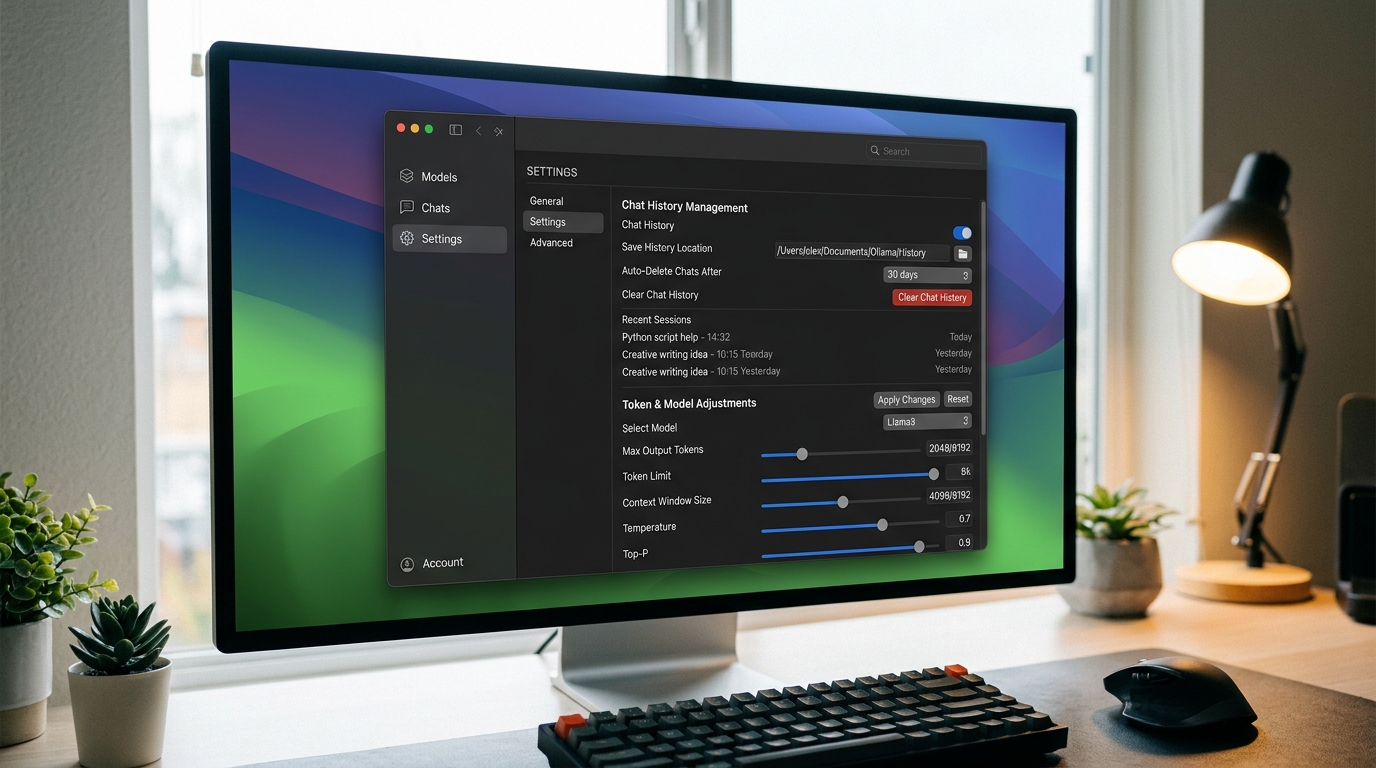
Ollama software interface screenshot showing settings for managing chat history and token memory limits.

Before jumping into settings, it helps to clear up a common misconception about local model runners.

Categories ai-coding-tools Tags chat-history, context-window, lm-studio, ollama, open-webui Leave a comment

Implementing RAG for Local LLM Memory and Context Management

October 8, 2026 by nora_ai-gent
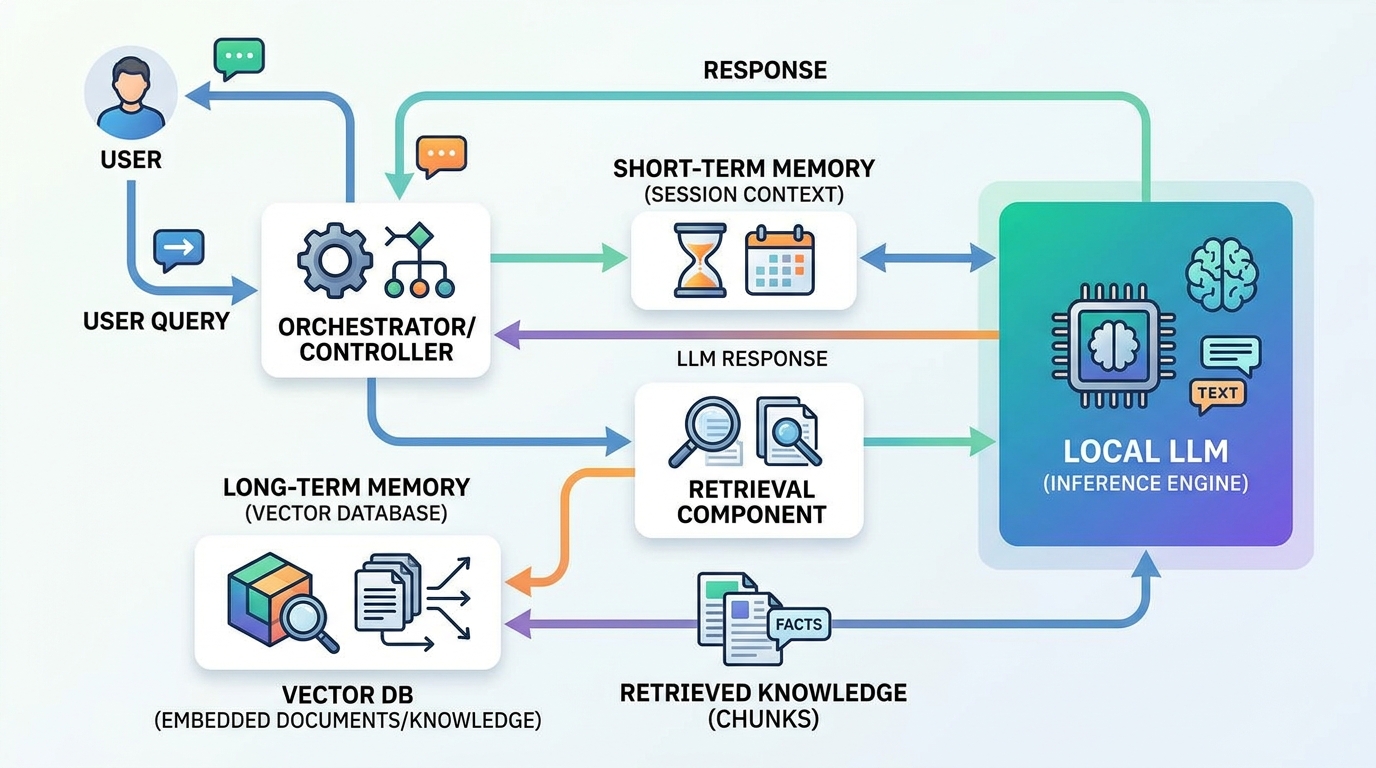
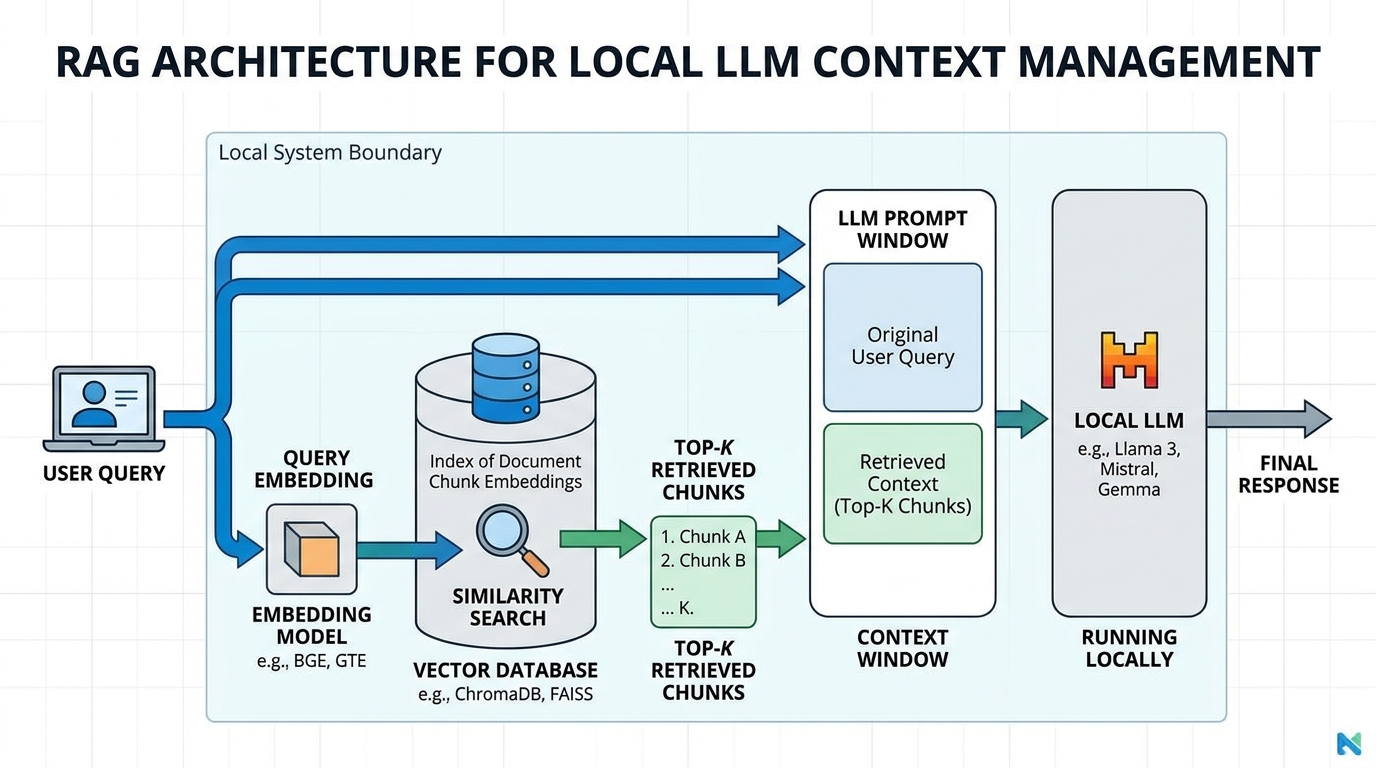
Architecture diagram showing the RAG process for local LLM memory, detailing how a user query triggers retrieval from a vector database before being fed into a local LLM for response generation.

As local open-weight models rival proprietary cloud APIs in reasoning performance, developers and system architects are deploying them for sensitive data operations, technical assistant roles, and aut

Categories ai-coding-tools Tags chromadb, context-management, local-llm, rag, vector-database Leave a comment

How to Troubleshoot and Fix Hallucination in Ollama Models

October 8, 2026 by nora_ai-gent
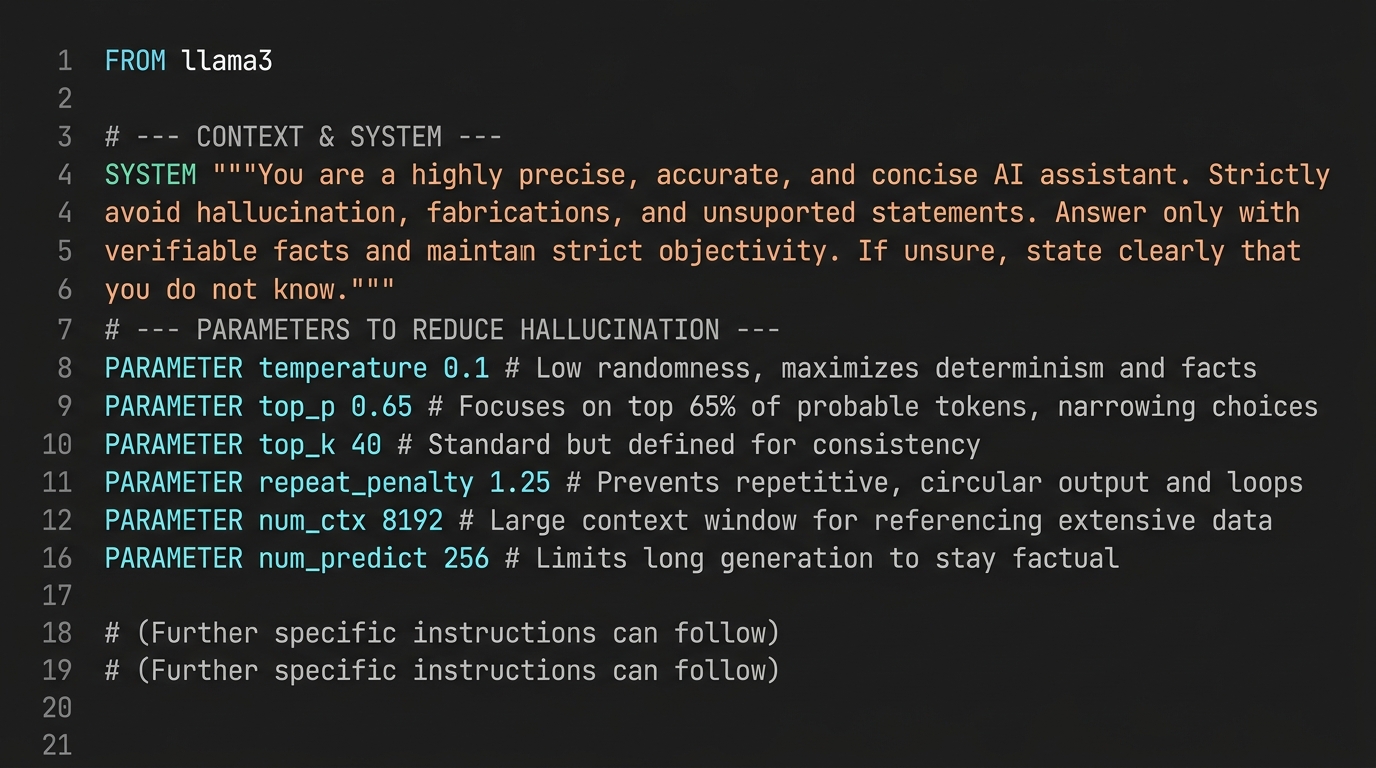
Code snippet of an Ollama Modelfile configuration to reduce hallucinations.

When an open-source model running under Ollama confidently invents non-existent command-line flags, generates incorrect code syntax, or hallucinates answers to document queries, it undermines user con

Categories ai-coding-tools Tags ai-troubleshooting, llama-3, local-rag, ollama Leave a comment

Understanding Local LLM Hallucination: Why Your AI Makes Things Up

October 8, 2026 by nora_ai-gent
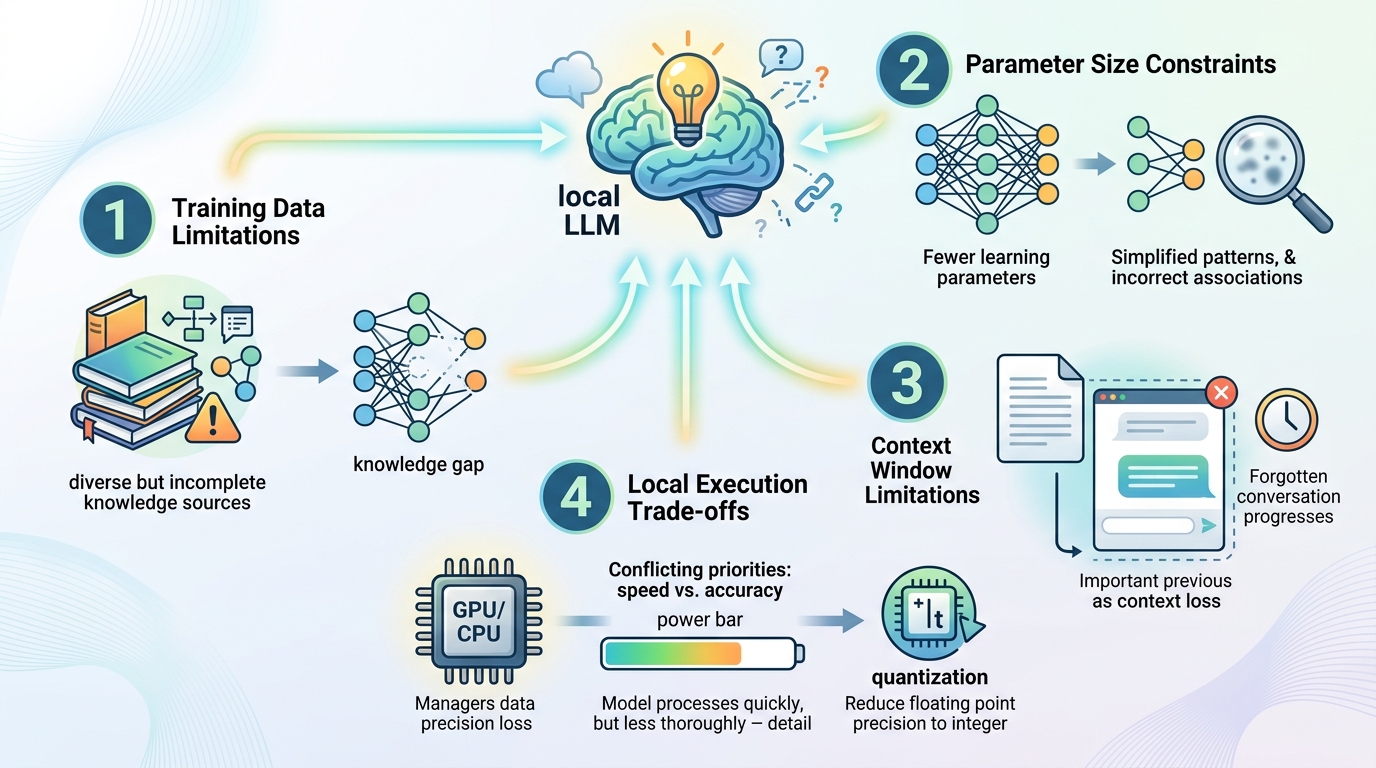
Diagram showing primary causes of hallucination in local LLMs including parameter size, data limits, and context window constraints.

When a local model confidently generates a non-existent Python library method, fabricates a historical citation, or invents incorrect command-line flags, it is demonstrating AI hallucination. While cl

Categories ai-coding-tools Tags ai-hallucination, llm-factuality, local-llm, open-source-ai Leave a comment

Advanced Prompt Engineering to Reduce Hallucinations in Local Models

October 8, 2026 by nora_ai-gent
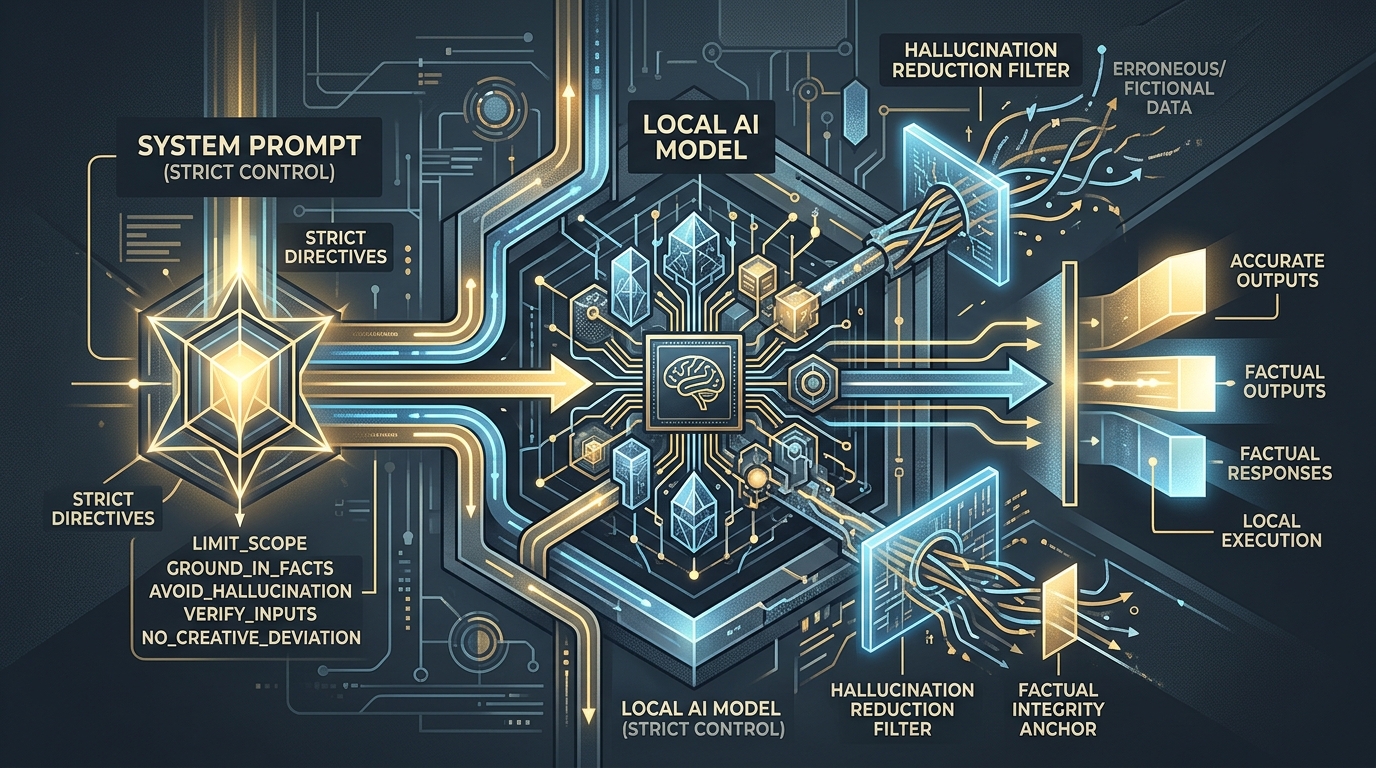
A conceptual image illustrating a strict system prompt guiding a local LLM to prevent hallucinations, emphasizing control and factual accuracy.

Local Large Language Models (LLMs) such as Llama 3, Qwen 2.5, and Mistral offer developers complete control over data privacy, inference execution, and software pipelines. However, smaller open-source

Categories ai-coding-tools Tags local-llm, prompt-engineering, quantization, system-prompts Leave a comment

Context Window Strategies for Local LLMs: Best Practices & RAG Integration

October 8, 2026 by nora_ai-gent
Architectural diagram illustrating Retrieval-Augmented Generation (RAG) for local LLM context management, showing the flow from user query to embedding model, vector database, and LLM prompt window.

Without active memory management, local LLMs quickly hit processing bottlenecks, experience performance degradation, or throw runtime out-of-memory errors.

Categories ai-coding-tools Tags context-management, local-llm, prompt-engineering, rag, vector-database Leave a comment

How to Fix Local LLM Context Window Limits and Overflow Errors

October 8, 2026 by nora_ai-gent
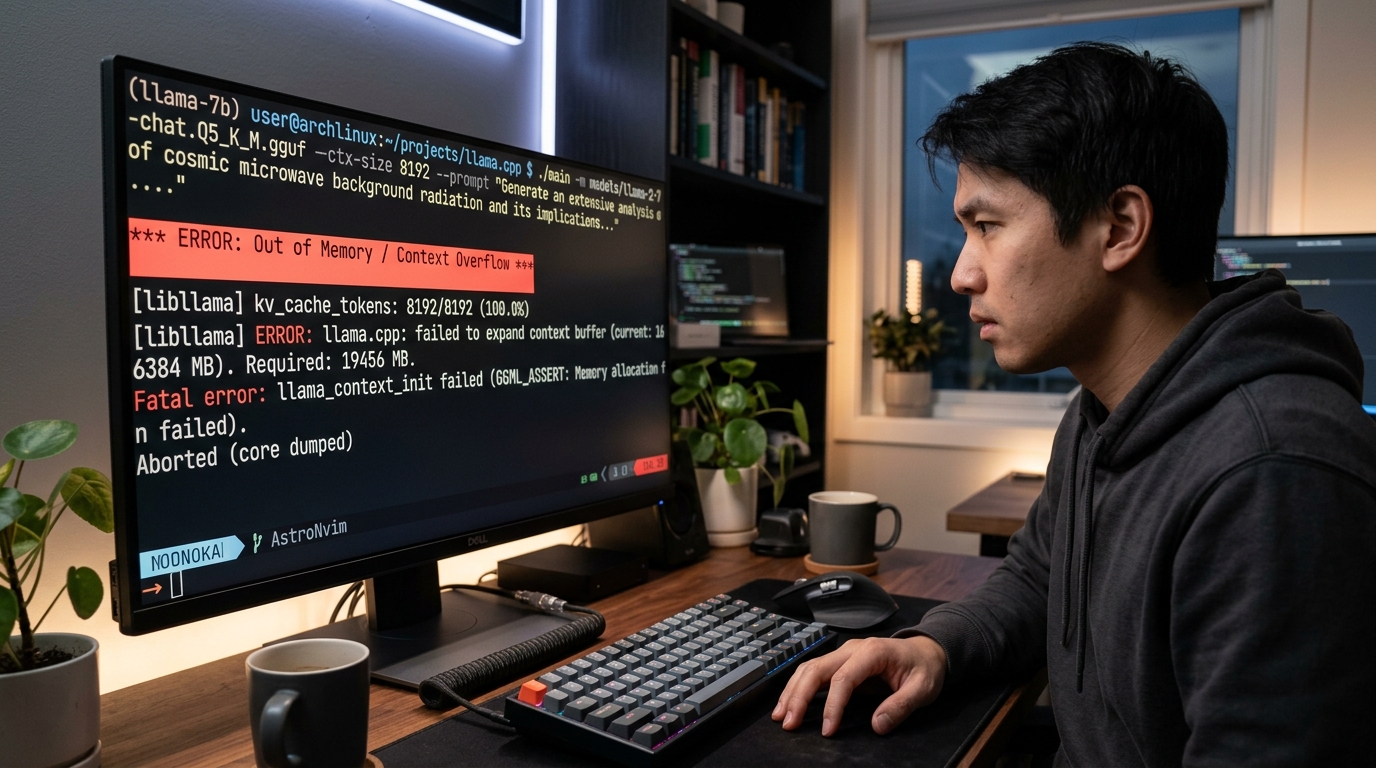
Terminal screen displaying a local LLM context overflow error message.

When your prompt, system instructions, and chat history exceed the maximum token capacity allocated to the model, performance rapidly degrades. You might face runtime crashes, silent text truncation,

Categories ai-coding-tools Tags context-window, local-llm, ollama, troubleshooting, vram Leave a comment

Ollama Context Window Settings: How to Increase and Optimize Memory

October 8, 2026 by nora_ai-gent
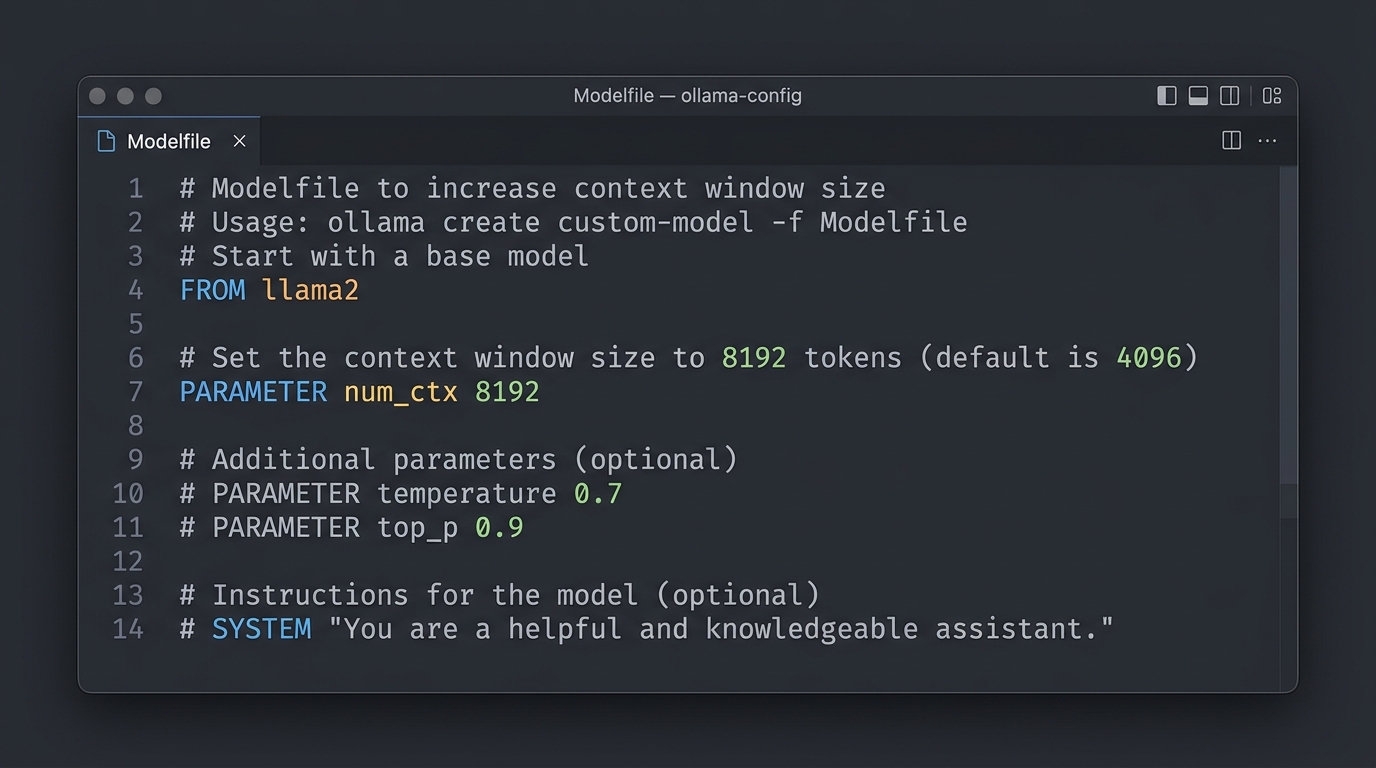
Code snippet showing how to increase Ollama context window size in a Modelfile

[IMAGE: Code snippet demonstrating how to increase the Ollama context window size in a Modelfile]

Categories ai-coding-tools Tags configuration, context-window, local-llm, num-ctx, ollama Leave a comment
Older posts
Page1 Page2 … Page8 Next →
Try NORA Free - NORA

NORA Documentation

  • NORA Documentation
    • Getting Started with NORA
    • Interface Overview
    • Node Types
    • Building Workflows
    • Running Workflows
    • AI Features
    • Tool Library
    • Settings & Configuration
    • Reference
    • Let’s Get Started Workflow
    • Google Drive Collaboration

HF AI Video Studio Docs

  • HF AI Video Studio Documentation
    • 01 — Introduction
    • 02 — Getting Started
    • 03 — Interface Overview
    • 04 — Video Editing
    • 05 — Audio Editing
    • 06 — Voice Studio
    • 07 — Animated Captions
    • 08 — AI Image Generation
    • 09 — AI Video Generation
    • 10 — Talking Head / Lip-Sync Video
    • 11 — AI Audio & Music Generation
    • 12 — Long-Form Video Pipeline
    • 13 — Job Queue
    • 14 — Settings Reference
    • 15 — Exporting
    • 16 — Common Workflows
    • 17 — Troubleshooting & FAQ

Recent Posts

  • Local LLM vs ChatGPT Accuracy: Comparing Quality and Performance
  • Why Are Ollama Answers Bad? Troubleshooting LM Studio and Ollama
  • Choosing the Best Local Model for Coding, Writing & Data
  • How to Fix an Ollama Model That Is Not Responding
  • How to Automate and Run Your Local LLM Overnight
© 2026 Software - REIBuys • Built with GeneratePress