
Unlocking Document Q&A with a Local LLM
Modern organizations generate vast volumes of unorganized text—PDF manuals, standard operating procedures, technical specifications, meeting transcripts, and internal project docs. Finding exact information within these sprawling archives using traditional keyword search is slow and frustrating. Traditional keyword search requires exact term matches, failing to understand semantic user intent or synthesize complex multi-document answers.
By pairing a document Q&A local LLM pipeline with Retrieval-Augmented Generation (RAG), teams can transform static folders into an interactive conversational intelligence layer. Instead of manually sifting through hundreds of pages, employees can converse directly with their document repositories, obtaining instant, factual answers backed by clear source citations.
In this guide, we explore how document retrieval generation operates on local hardware, how to execute local LLM document search, and how to build a fully private AI chatbot for your organization.
How Document Retrieval Generation Actually Works
To understand how a document Q&A local LLM interface works, we must look at the mechanics of document retrieval generation. Rather than feeding thousands of pages directly into a model’s prompt window—which causes high memory usage, high cost, and hallucination—the process breaks down into two coordinated stages: Semantic Retrieval and Grounded Generation.
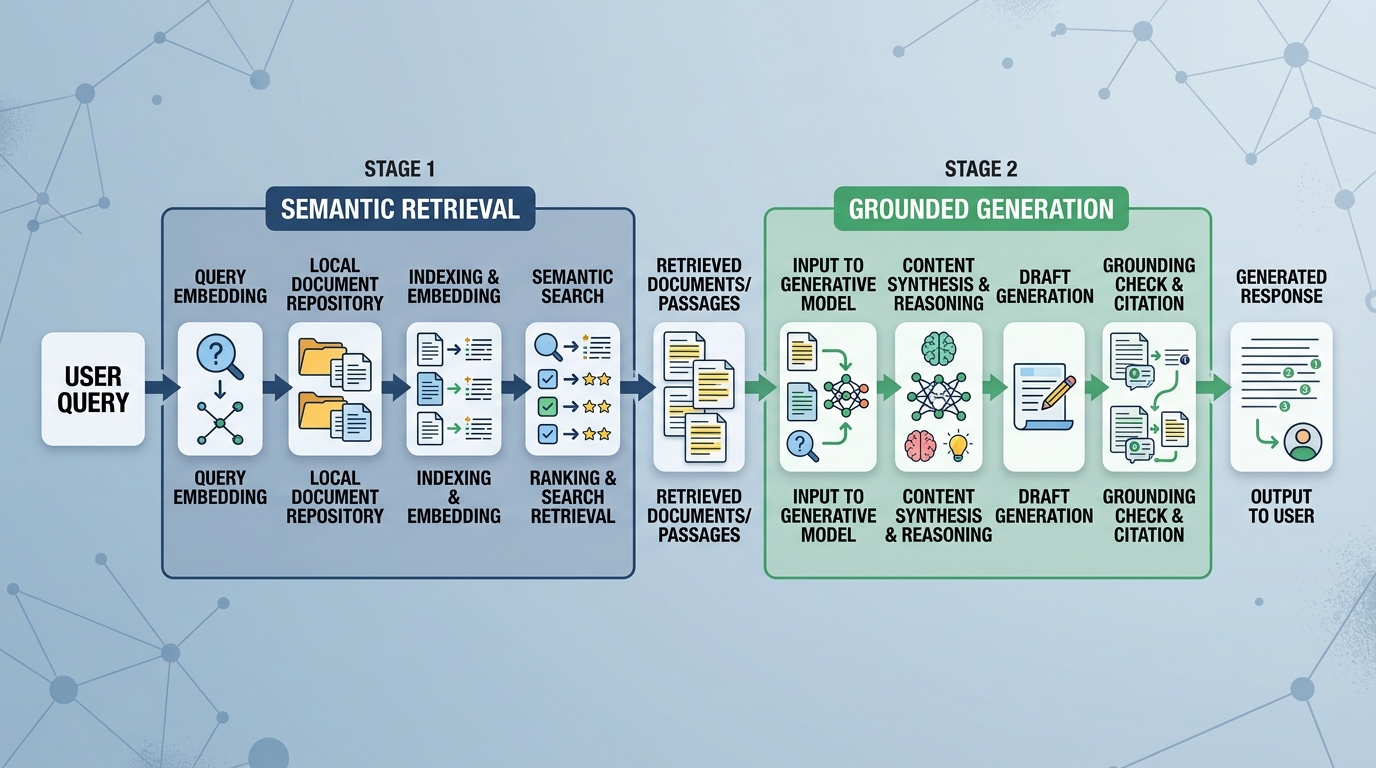
A flowchart detailing the two stages of document retrieval generation: Dense Semantic Retrieval and Grounded Response Generation.
Stage 1: Dense Semantic Retrieval
- Parsing & Chunking: Raw files (PDFs, DOCX, TXT, Markdown) are loaded and chunked into manageably sized text segments (e.g., 500–1,000 characters).
- Vector Embedding: A local embedding model converts text chunks into mathematical vectors stored in a local vector database.
- Vector Search: When a user asks a question, the query string is vectorised using the exact same embedding model. The system calculates vector distance (using cosine similarity) to identify the top $K$ most relevant text chunks from the vector database.
Stage 2: Grounded Response Generation
- Prompt Assembly: The retrieved text chunks are formatted into a structured context prompt alongside strict instruction boundaries.
- Inference: A local LLM reads the retrieved context and generates a precise answer using only the facts contained within those retrieved snippets.
- Attribution: The system returns the generated answer alongside source metadata (such as document name and page number) so the user can verify the answer against original source documents.
Exploring Local LLM Document Search Capabilities
Implementing local LLM document search provides major capabilities that go far beyond conventional keyword-matching search engines:
- Semantic Intent Matching: Querying “What are our server backup rules?” retrieves documents discussing “disaster recovery policies” and “snapshot schedules”, even if the word “backup” never appears in the text.
- Multi-Document Synthesis: The local LLM aggregates complementary facts across disparate files—combining legal terms from one document with technical specs from another—to construct a unified summary.
- Natural Language Summarization: Complex technical manuals or dense policy manuals are synthesized into concise, bulleted action items tailored to the user’s expertise level.
- Contextual Citation: Answers reference the exact page, section, or file name where supporting information resides, establishing complete transparency and trust.
If you are looking to install and build RAG with Ollama locally, setting up these document search capabilities requires minimal local infrastructure.
Setting Up a Private AI Chatbot for Internal Use
Building a private AI chatbot gives your team a clean, familiar chat interface (similar to ChatGPT) while guaranteeing that all underlying files and chat logs remain strictly contained on internal hardware.
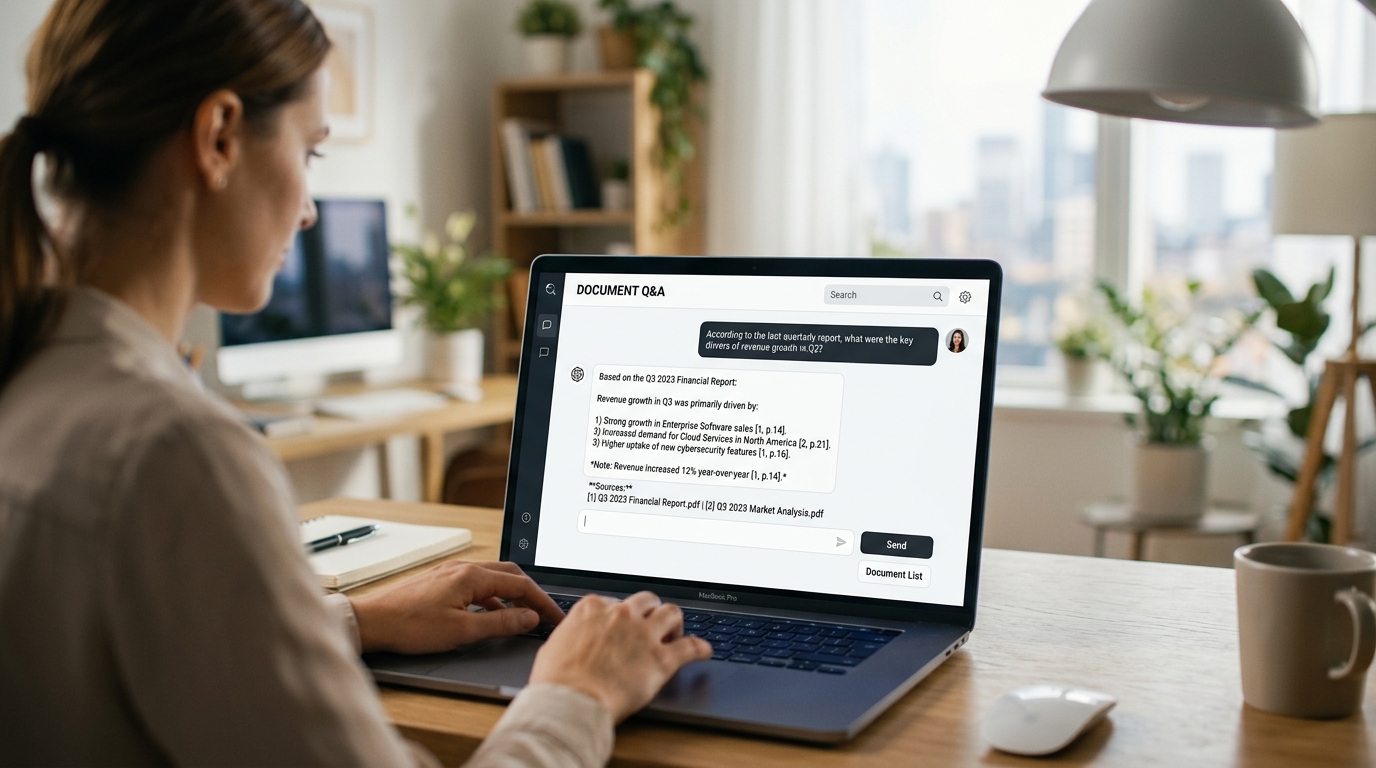
An example of a private AI chatbot interface, demonstrating how users can interact with local documents for Q&A.
Core Architectural Layers of a Private Chatbot
A production-ready internal chatbot consists of three core software layers:
- User Interface Layer: Open-source web interfaces such as Open WebUI, Chainlit, or Gradio provide user management, chat history, file attachment buttons, and direct citation displays.
- Orchestration & Retrieval Layer: Frameworks like LangChain or LlamaIndex manage vector database connections, document loaders, memory buffers, and context prompt formatting.
- Local Inference Engine: Local platforms like Ollama, vLLM, or LM Studio serve local generative models and embedding models on internal hardware.
By running this complete software stack on internal workstations or local servers, enterprise teams can freely query sensitive corporate data. To learn more about corporate data protection architectures, deploy a private RAG system to protect sensitive data.
Running RAG on Local Documents
When implementing RAG on local documents, selecting the appropriate generative language model is critical. Different open-source models excel at different document processing tasks depending on parameter size and context window capabilities.
Choosing the Best Local LLM for Q&A Workloads
Here is an overview of top open-source local language models ideal for local LLM for Q&A workloads in 2026:
- Llama 3.2 (3B / 8B): Outstanding general-purpose model with exceptional instruction-following accuracy, strong reasoning, and fast token generation speeds on consumer hardware.
- Mistral / Mixtral (7B / 8x7B): Renowned for technical document understanding, precise code analysis, and high reasoning throughput.
- Qwen 2.5 (7B / 14B / 32B): Exceptional performance across multilingual document sets, dense technical specifications, and structured data tables.
- Phi-3.5 / Phi-4 (3.8B / 14B): Highly efficient small language models engineered by Microsoft for dense logical reasoning and compact memory footprints.
For most standard desktop environments with 16 GB to 32 GB of RAM, a 7B or 8B parameter model quantized to 4-bit (Q4_K_M) provides the ideal balance of accuracy, memory usage, and inference speed.
Overcoming Challenges with Local Document Processing
While running a local document Q&A pipeline offers complete privacy and speed, technical teams must plan for common operational challenges:
1. Complex File Formatting (PDFs and Tables)
Standard text extraction tools often scramble multi-column layouts, tables, and embedded images in PDF documents.
* Solution: Utilize layout-aware PDF parsers such as pdfplumber, Unstructured, or PyMuPDF. For complex tables, extract tables into Markdown format before vector embedding.
2. Large Context Windows vs. Hardware Limits
Injecting too many document chunks into a local LLM prompt can saturate GPU VRAM or exceed model context limits, leading to high latency or response truncation.
* Solution: Implement strict context limits ($K=3$ to $K=5$ chunks) and utilize hybrid search with local re-ranking to filter out noise before passing prompts to the LLM.
3. Out-of-Date Answers
If source documents are updated or removed on local network shares, the vector store index can become stale.
* Solution: Implement scheduled script triggers that detect local file checksum changes and update vector database indexes incrementally.
Frequently Asked Questions (FAQ)
What is the best local LLM for document Q&A?
In 2026, Llama 3.2 (8B) and Qwen 2.5 (7B/14B) are widely considered top choices for local document Q&A due to their strong instruction following, accurate context adherence, and low memory requirements.
How does a local LLM answer questions from local documents?
The local LLM does not train on your documents directly. Instead, a local retriever finds relevant document text chunks using vector search and injects those exact text chunks into the context prompt sent to the local LLM. The LLM reads the context and summarizes the answer.
Can a local document Q&A system handle scanned PDF files?
Yes, but scanned PDFs require an Optical Character Recognition (OCR) step before text chunking. Open-source libraries like Tesseract or ocrmypdf convert scanned image pages into plain text before passing them into the RAG ingestion pipeline.
Is an internet connection required to run local document search?
No. Once the local LLM runtime (e.g., Ollama), language models, and Python packages are installed, all text parsing, vector searching, and response generation occur 100% offline on your host computer.
How do I prevent a local LLM from hallucinating when documents don’t contain the answer?
You can control hallucinations by enforcing system prompt constraints, instructing the local LLM: “Answer the user query ONLY using the provided document context. If the answer is not contained in the context, explicitly state ‘I cannot find that information in the provided files.'”