How to Automate and Run Your Local LLM Overnight
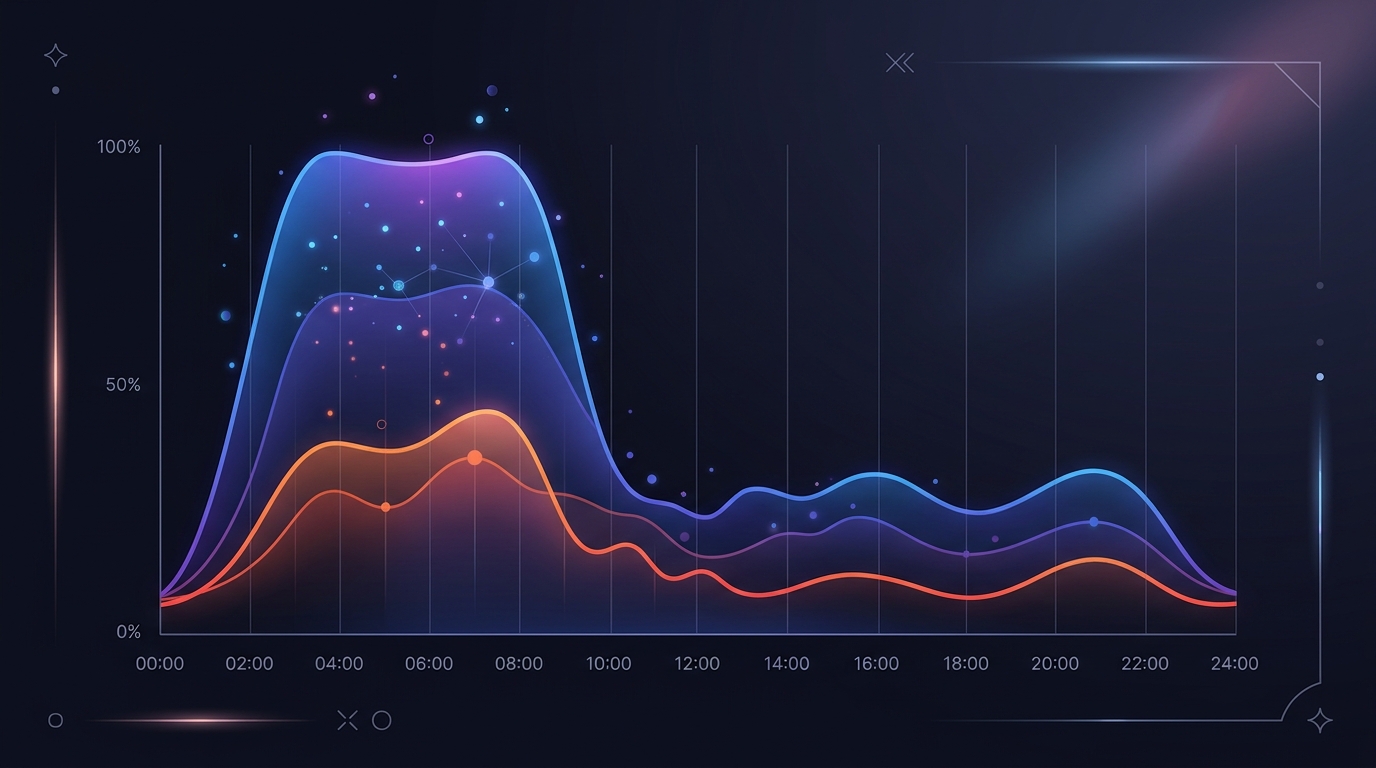
High-performance GPUs and workstation CPUs represent a major hardware investment. For developers, data engineers, and homelab enthusiasts running local Large Language Models (LLMs), these expensive co
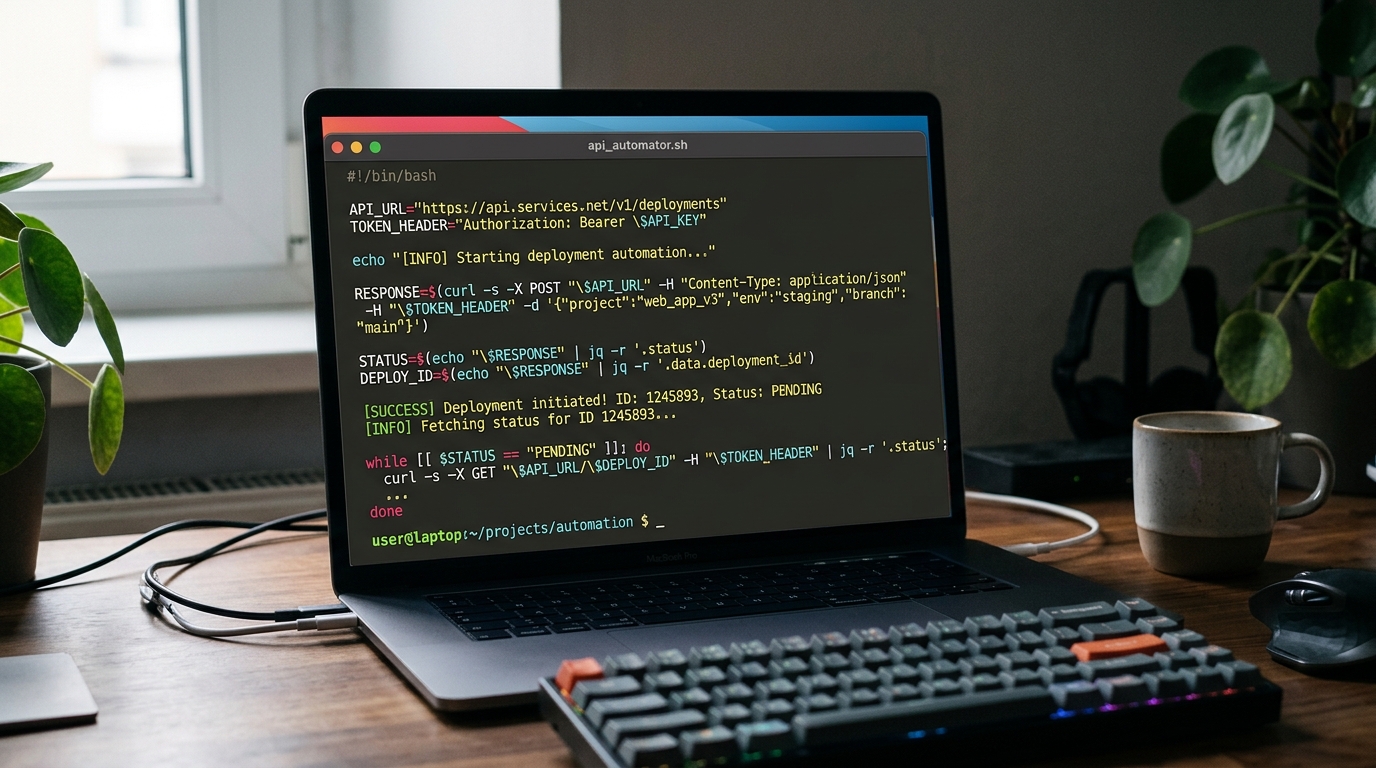
Ollama has emerged as one of the most popular platforms for running Large Language Models locally on Linux, macOS, and Windows. By packaging model weights, system prompts, quantization settings, and i
Large Language Models (LLMs) have evolved beyond interactive chat interfaces into powerful engines for autonomous computational pipelines. While web-based chatbots like ChatGPT, Claude, and Gemini int
Automating local Large Language Model (LLM) execution transforms manual prompt engineering into reliable, background-driven workflows. Whether you need to digest daily server logs, generate overnight