
Advanced Prompt Engineering to Reduce Hallucinations in Local Models
Local Large Language Models (LLMs) such as Llama 3, Qwen 2.5, and Mistral offer developers complete control over data privacy, inference execution, and software pipelines. However, smaller open-source models executed on local GPUs exhibit a higher propensity for factual errors and ungrounded generation compared to massive cloud endpoints.
While general methods to mitigate local AI hallucination focus heavily on basic parameter adjustments like temperature and top-p tuning, developer-level reliability requires deeper control.
This advanced technical guide explores how system prompt design, context window management, quantization mechanics, and advanced reasoning prompting (such as Chain of Thought and Self-Correction) can be engineered to minimize hallucination in local LLM deployments.
How System Prompts Control Hallucination in Local Models
System prompts serve as the primary behavioral architecture for open-source models. While user prompts define the immediate task, the system prompt governs how the model handles uncertainty, missing facts, and boundary enforcement.
Unaligned or loosely configured local models often attempt to satisfy user requests at all costs. If a model lacks precise factual information in its parameters, its default behavior is to predict the most plausible-sounding sequence of tokens, resulting in confabulation. System prompts reframe this behavior by giving the model explicit instructions on how to evaluate confidence before generating output.
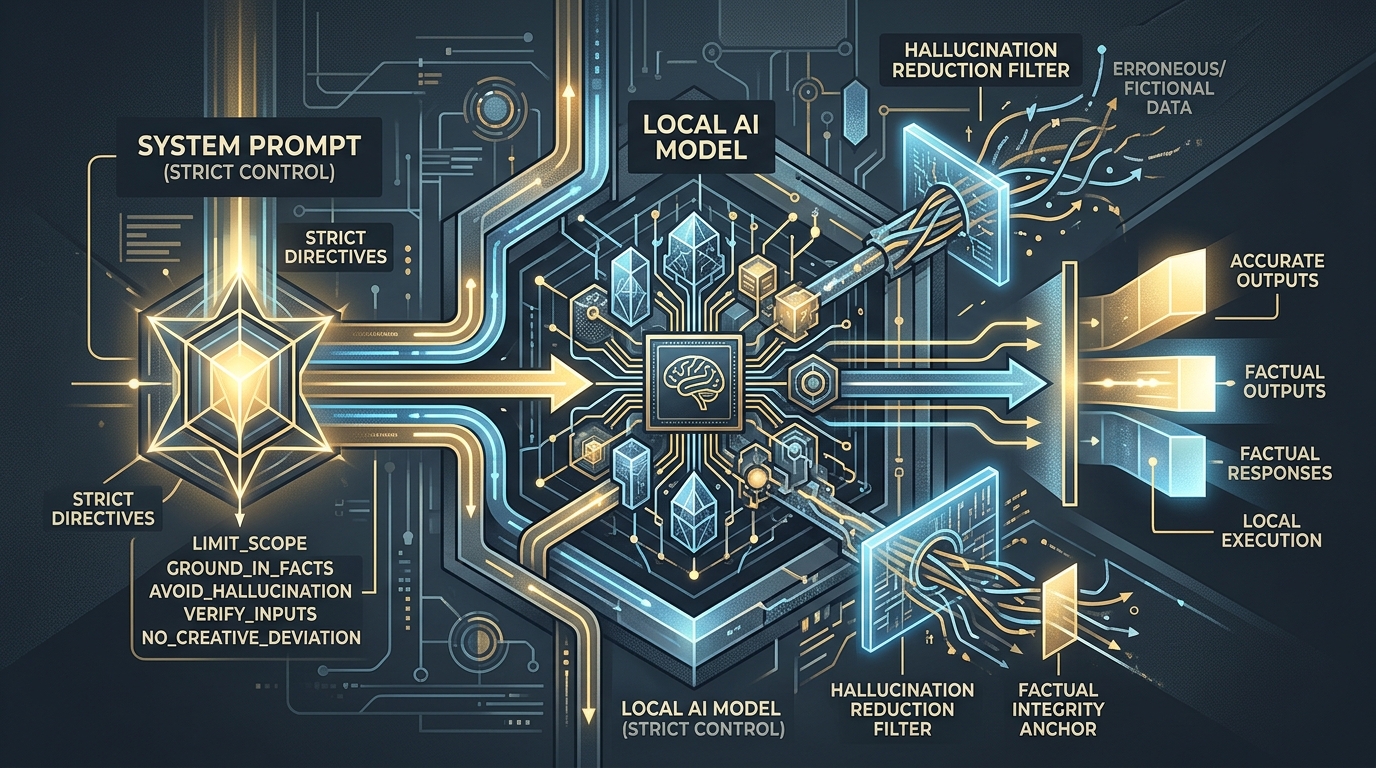
A strict system prompt acts as a behavioral architecture, guiding local models to prioritize factual integrity and refuse ungrounded generation.
Crafting the Perfect Anti-Hallucination System Prompt
An effective anti-hallucination system prompt for local models must address three core dimensions: boundary definition, explicit refusal permissions, and strict context grounding.
Below is an engineered, production-ready system prompt template designed specifically for open-source local models:
You are an expert AI assistant operating under strict factual integrity constraints.

OPERATIONAL RULES:
1. TRUTH-GROUNDING: Rely ONLY on established, verifiable facts or explicitly provided context. Do NOT extrapolate beyond confirmed knowledge.
2. REFUSAL PROTOCOL: If you are asked a question that you cannot answer with high factual confidence, or if the provided context lacks the necessary information, state: "I do not have sufficient verifiable data to answer this question accurately."
3. NO GUESSING: Never invent code syntax, function signatures, library methods, URLs, or historical citations.
4. UNCERTAINTY MARKERS: If providing an estimate or logical derivation, explicitly prefix the statement with "INFERENCE:" to distinguish it from verified facts.

FAILURE TO COMPLY WITH THESE RULES WILL RESULT IN PIPELINE FAILURE.
When applying system prompts locally, ensure that your inference runner (such as Ollama or llama.cpp) uses the exact prompt template format required by the underlying model (e.g., <|start_header_id|>system<|end_header_id|> for Llama 3). (llama.cpp) If system prompts are improperly formatted, the model may treat system instructions as standard conversational text, diminishing its instruction-following compliance. If you experience issues with instruction adherence, see our troubleshooting guide on enforcing prompt structures.
The Role of the Context Window in Local AI Hallucination
A major source of unexpected factual drift in local models is context window mismanagement. While modern open-source models advertise context limits ranging from 8k to 128k tokens, local GPU memory limits and parameter scale introduce severe attention bottlenecks over long sequences.
Avoiding Attention Degradation in Long Contexts
As context length increases, self-attention mechanisms in small models (7B to 14B parameters) experience attention dilution. The attention scores assigned to critical early instructions—such as system prompts or key source facts—become diluted across thousands of intermediate tokens.
To prevent context-induced hallucinations:
- Keep Context Windows Tight: Do not allocate a 32k context window if your task only requires 4k tokens. Restricting the active context window reduces memory usage and keeps self-attention concentrated on high-value tokens.
- Position Key Instructions at the Periphery: Research into LLM attention mechanisms shows that models attend best to tokens located at the very beginning and very end of the context window (the “lost in the middle” phenomenon). (“lost in the middle” phenomenon) Always place your strict system instructions at the top, and put reference context snippets directly before the user query at the bottom.
- Implement Dynamic Context Pruning: In long multi-turn chats, dynamically prune or summarize older conversation turns rather than accumulating raw context logs.
Does Quantization Cause Hallucination in Local LLMs?
To execute local LLMs on consumer GPUs like an NVIDIA RTX 4090 (24GB VRAM) or Apple Silicon Macs, models are typically compressed using quantization. (NVIDIA RTX 4090) Quantization reduces the bit-precision of model weights from 16-bit floating-point (FP16) down to 8-bit, 4-bit, or even 2-bit integers.
Understanding the mechanics of understanding quantized models is vital when assessing factual reliability.
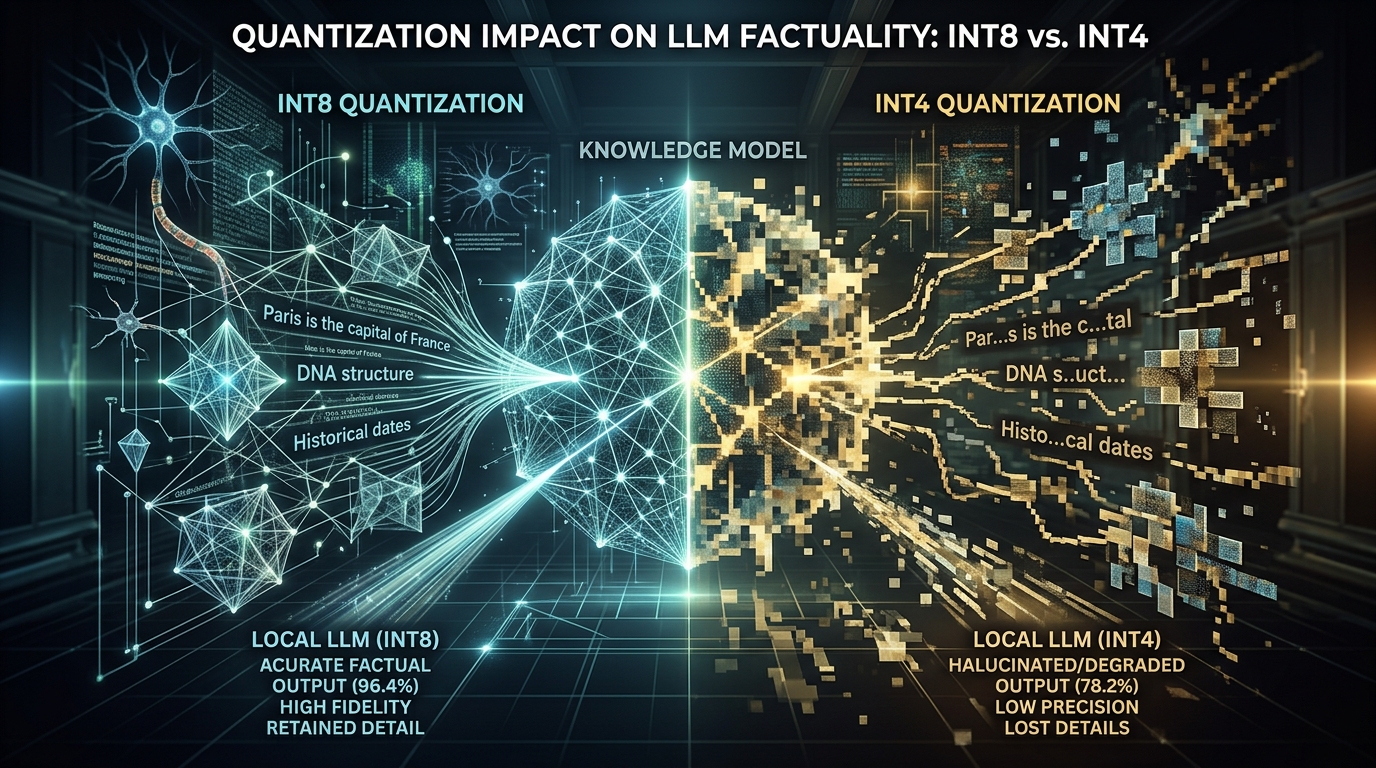
Quantization levels significantly influence a local LLM’s factual precision and recall, with lower bit-precision leading to increased degradation.
Comparing INT4, INT8, and FP16 Factuality
Quantization affects model capability unevenly. General linguistic fluency remains remarkably stable even at aggressive quantization levels, but factual recall and mathematical reasoning degrade significantly when precision drops below 4 bits.
| Quantization Format | Relative VRAM Footprint | Impact on Language Fluency | Impact on Factual Precision & Recall | Recommended Use Case |
|---|---|---|---|---|
| FP16 / BF16 | 100% (Baseline) | Baseline (Highest) | Baseline (Zero Degradation) | Research, High-precision benchmark evaluation |
| Q8_0 (8-bit) | ~55% | Imperceptible Loss | < 1% Accuracy Loss | Fact-critical local pipelines, code generation |
| Q4_K_M (4-bit) | ~30% | Minimal Loss | 2% – 5% Accuracy Loss | Optimal balance for general local development |
| Q3_K_S (3-bit) | ~22% | Moderate Loss | 10% – 20% Accuracy Loss | Highly creative writing; avoid for factual Q&A |
| Q2_K (2-bit) | ~15% | High Degradation | Severe Hallucination Spike | Not recommended for production or factual tasks |
Technical Takeaway: When building local workflows where factual precision is paramount, avoid Q2 or Q3 quantization levels. Standardize on Q4_K_M as your minimum baseline, or step up to Q8_0 if VRAM permits.
Fine-Tuning vs. Prompting to Reduce Hallucination
When facing persistent hallucinations in specialized domains (e.g., medical data, internal codebases, proprietary API schemas), developers often debate whether to fine-tune a model or rely on prompt engineering with RAG.
                  ┌───────────────────────────────────────────────┐
                  │ Does the model need NEW domain knowledge?     │
                  └───────────────────────┬───────────────────────┘
                                          │
                         ┌────────────────┴────────────────┐
                         ▼                                 ▼
                     [ YES ]                            [ NO ]
                         │                                 │
                         ▼                                 ▼
         ┌───────────────────────────────┐ ┌───────────────────────────────┐
         │ Ground with RAG & System      │ │ Optimize System Prompts,      │
         │ Context Injection             │ │ Temperature=0.0 & Few-Shot    │
         └───────────────┬───────────────┘ └───────────────────────────────┘
                         │
                         ▼
         ┌───────────────────────────────┐
         │ Does it still fail style or   │
         │ format compliance?            │
         └───────────────┬───────────────┘
                         │
                         ▼
         ┌───────────────────────────────┐
         │ Apply LoRA / QLoRA Fine-      │
         │ Tuning for Style/Tone         │
         └───────────────────────────────┘
- Prompt Engineering & RAG (Recommended for Facts): Fine-tuning a model on factual data embeds facts into implicit parameter weights, which can still be misremembered or mixed up during inference. RAG injects explicit text snippets directly into the context window, allowing prompt engineering to enforce exact factual recall.
- LoRA / Fine-Tuning (Recommended for Style & Format): Fine-tuning (via QLoRA) is highly effective for teaching a local model a specific output syntax, tone, or schema, but it should not be relied upon as the sole solution for reducing factual hallucination on dynamic data.
Advanced Techniques: Chain of Thought & Self-Correction
For complex reasoning tasks, prompting a local model to generate an answer immediately forces it to commit to a high-probability initial token, which can pull the entire generation into a hallucinated sequence. Incorporating advanced multi-step prompting techniques allows local models to evaluate logic before producing a final answer.
1. Chain-of-Thought (CoT) Grounding
Chain-of-Thought prompting forces the model to display its intermediate reasoning steps before delivering the final result. Breaking complex queries into explicit analytical steps dramatically reduces logical jumps and confabulation.
Example CoT Prompt Structure:
User: Determine if the following Python function contains any deprecated methods in Python 3.12:

[Code Snippet]

Instructions:
1. List all imported modules and functions used in the code.
2. For each function, verify its status in the standard library.
3. State whether any method is deprecated.
4. Provide the final determination.

Think step-by-step before providing your final conclusion.
2. Self-Correction & Verification Loops
Because local LLM inference is fast and free of external API fees, you can run multi-pass verification pipelines locally.
In a two-stage verification workflow:
1. Drafting Pass: The local LLM generates an initial response at temperature=0.2.
2. Critique Pass: A secondary system prompt feeds the generated draft back into the local model, asking it to audit the draft for factual inconsistencies or ungrounded claims.
Self-Correction System Prompt:
“You are an automated factual auditor. Review the following generated draft response against the reference context. Identify any statements that are NOT explicitly supported by the reference text. Output a corrected, strictly factual response.”
By running a fast, automated critique pass, you can catch up to 80% of hallucinated errors before output is delivered to end users.
Frequently Asked Questions
Can prompt engineering eliminate 100% of local LLM hallucinations?
No. Prompt engineering can significantly reduce hallucinations caused by parameter noise or weak guardrails, but it cannot fix fundamental knowledge gaps or severe quantization degradation. Combining prompt engineering with local RAG retrieval provides the highest level of accuracy.
What is the best quantization level for technical and coding tasks?
Q4_K_M is the recommended sweet spot for general local execution. For highly technical tasks, API code generation, or complex logic where subtle weight precision matters, Q8_0 or FP16 will yield noticeably lower error rates if your GPU VRAM supports it.
Why does Chain-of-Thought prompting reduce hallucinations in local models?
Chain-of-Thought (CoT) prompting provides the model with additional token processing steps (“scratchpad memory”) to establish logical dependencies before generating the final answer. This prevents the model from locking into an incorrect early token trajectory.