Context Window Strategies for Local LLMs: Best Practices & RAG Integration
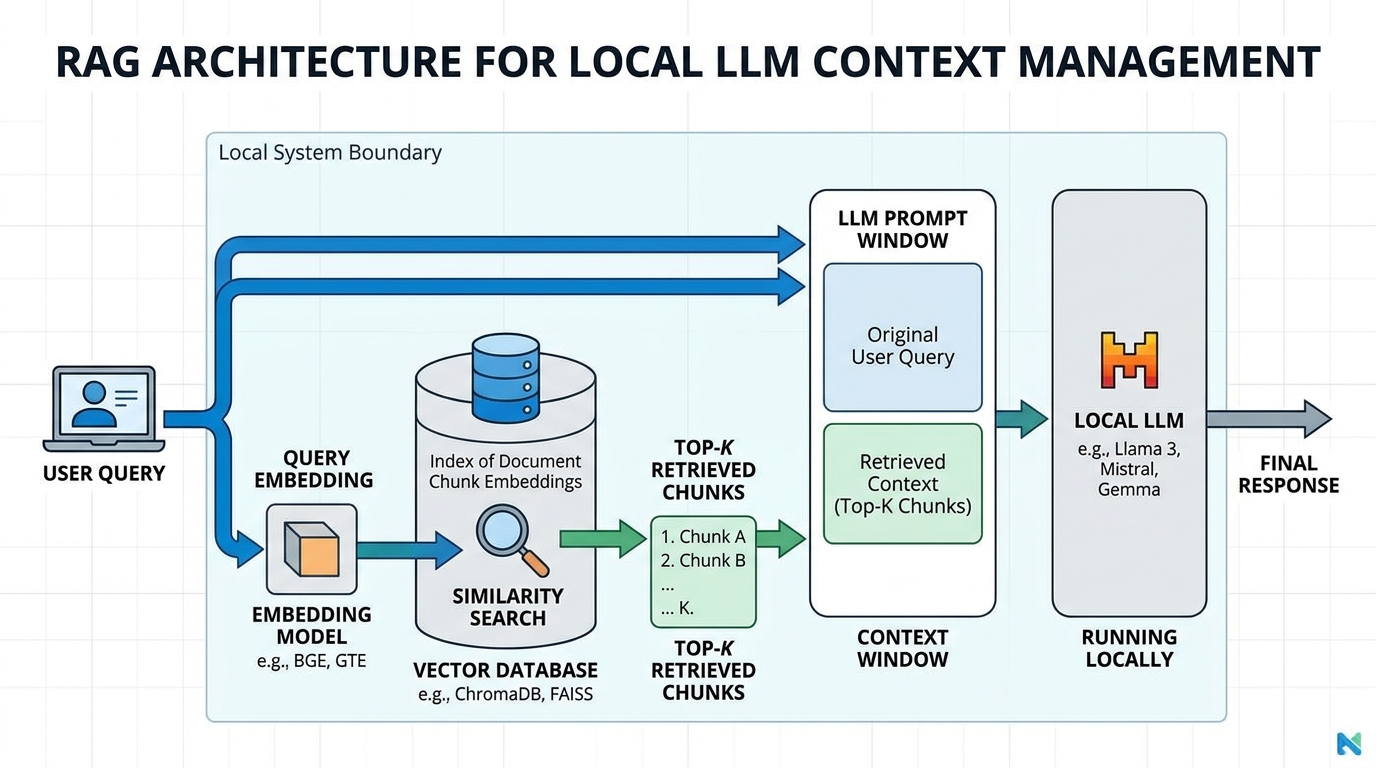
Without active memory management, local LLMs quickly hit processing bottlenecks, experience performance degradation, or throw runtime out-of-memory errors.
Without active memory management, local LLMs quickly hit processing bottlenecks, experience performance degradation, or throw runtime out-of-memory errors.
The Ultimate Guide to System Prompts for Local LLMs As developers and privacy-focused technology teams move away from third-party APIs toward open-source models like Llama 3, Mistral, and Gemma, crafting an effective system prompt local llm configuration has become a critical engineering skill. While commercial AI platforms rely on massive scale and heavy RLHF (Reinforcement … Read more
How to Fix a Local LLM That Isn’t Following Instructions Running large language models (LLMs) on local hardware provides unparalleled privacy, zero API costs, and total control over your AI stack. However, many developers and AI enthusiasts quickly encounter a frustrating roadblock: a local LLM not following instructions consistently. You might prompt your model to … Read more
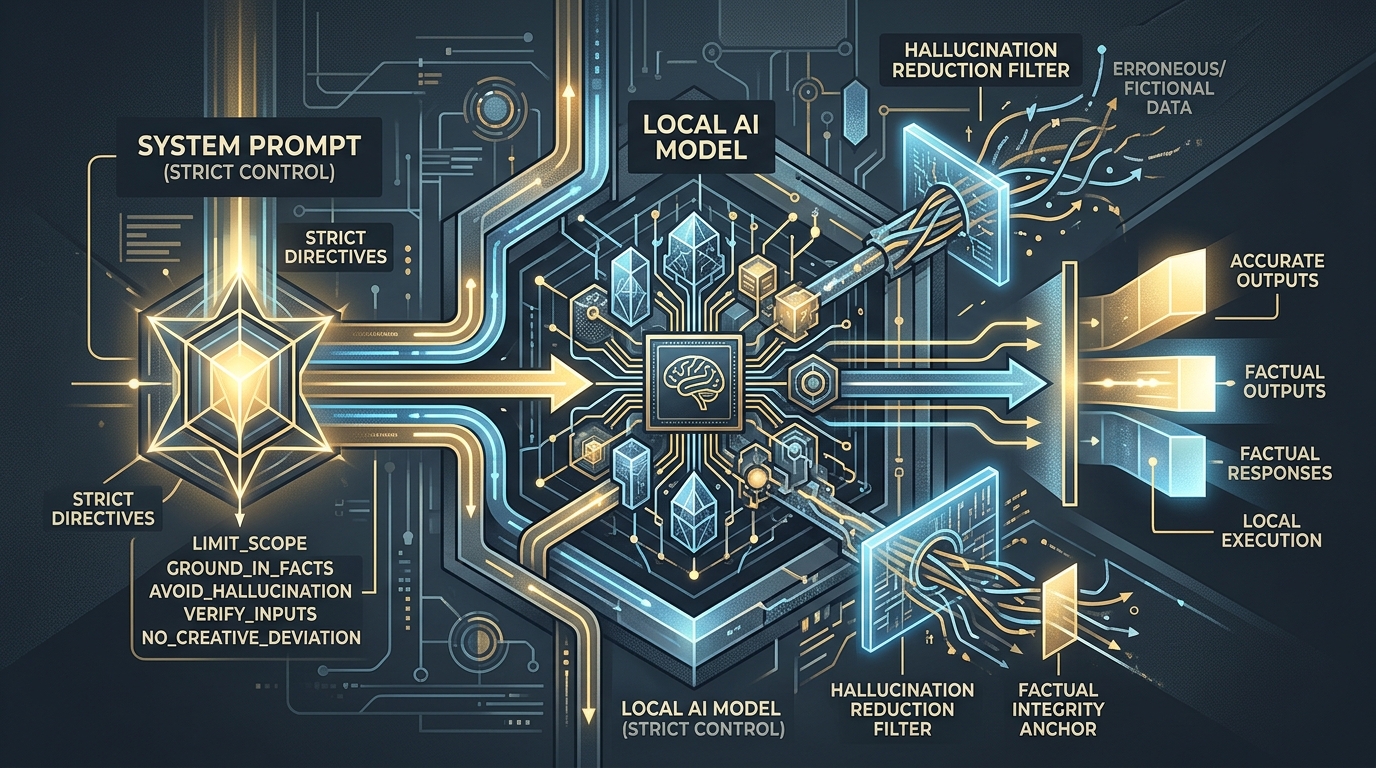
Local Large Language Models (LLMs) such as Llama 3, Qwen 2.5, and Mistral offer developers complete control over data privacy, inference execution, and software pipelines. However, smaller open-source
As artificial intelligence architectures transition from static conversational single-turn chats to autonomous multi-step reasoning agents, managing the information density in Large Language Model (LL
Stepping into the world of artificial intelligence can feel overwhelming. With terminology like “neural networks,” “transformer models,” “hyperparameters,” and “vector databases” thrown around daily,
Integrating artificial intelligence into modern software stacks requires more than copying prompt strings into a web interface. Software engineers must write resilient, maintainable code capable of ha
Anthropic’s Claude 3.5 Sonnet and Claude 3 Opus models offer standard 200,000-token context windows (and specialized enterprise windows reaching up to 1,000,000 tokens). This expanded capacity has tra

Prompt engineering has evolved beyond crafting clever, conversational instructions for single-turn AI chatbots. In 2026, prompt design is a software engineering discipline centered on token optimizati
But there is a right way and a wrong way to do this. AI-generated ops scripts run with real privileges against real systems, and a plausible-looking script that mishandles an edge case can do real dam