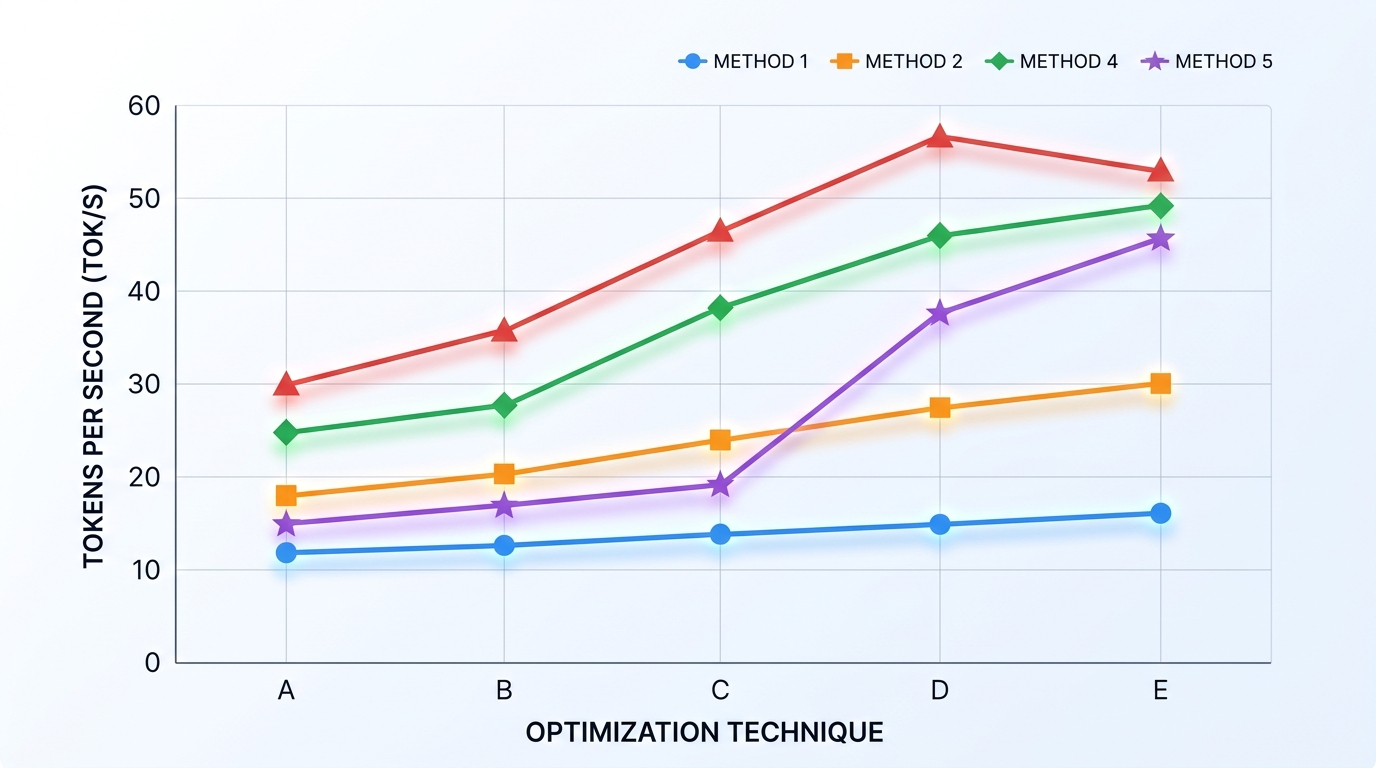
Understanding the Quantization Impact on Speed for Local LLMs
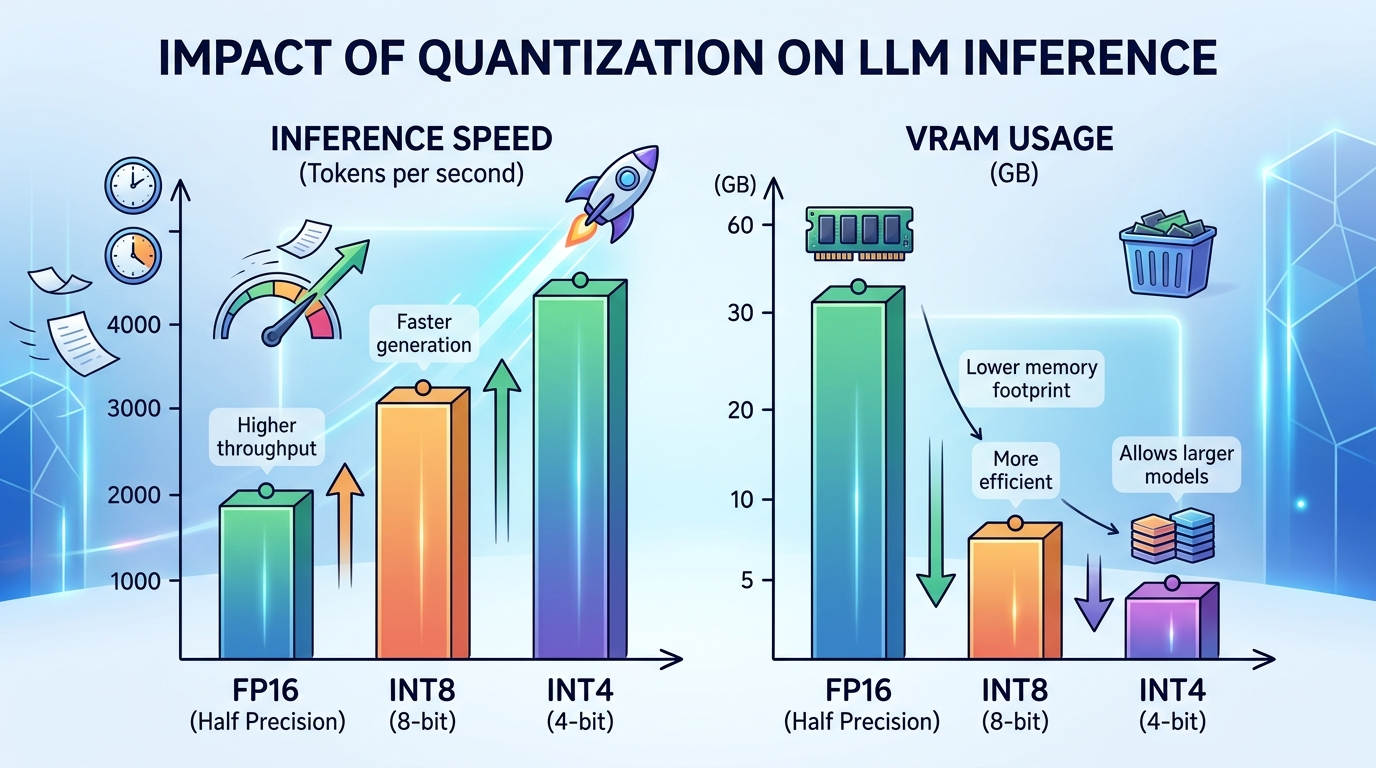
When configuring local large language models, performance depends on three core parameters: total parameter size, quantization level, and context window allocation. Tuning these settings determines wh