Skip to content
Software – REIBuys
  • Home
    • More Apps
      • NORA Desktop App
        • NORA Documentation
        • NORA (EULA)
      • HF AI Video Studio
        • HF AI Video Studio Documentation
    • Blog
    • Support

local-ai

How to Troubleshoot Slow Ollama Setups on Mac and Windows

September 20, 2026 by REIBuys Engineering Team

Ollama has become one of the most popular platforms for running open-source large language models locally. Its simple CLI interface, unified REST API, and automatic hardware detection make model deplo
Categories local-ai Tags apple-silicon, macos, ollama, windows, wsl2 Leave a comment

Understanding the Quantization Impact on Speed for Local LLMs

September 20, 2026 by REIBuys Engineering Team
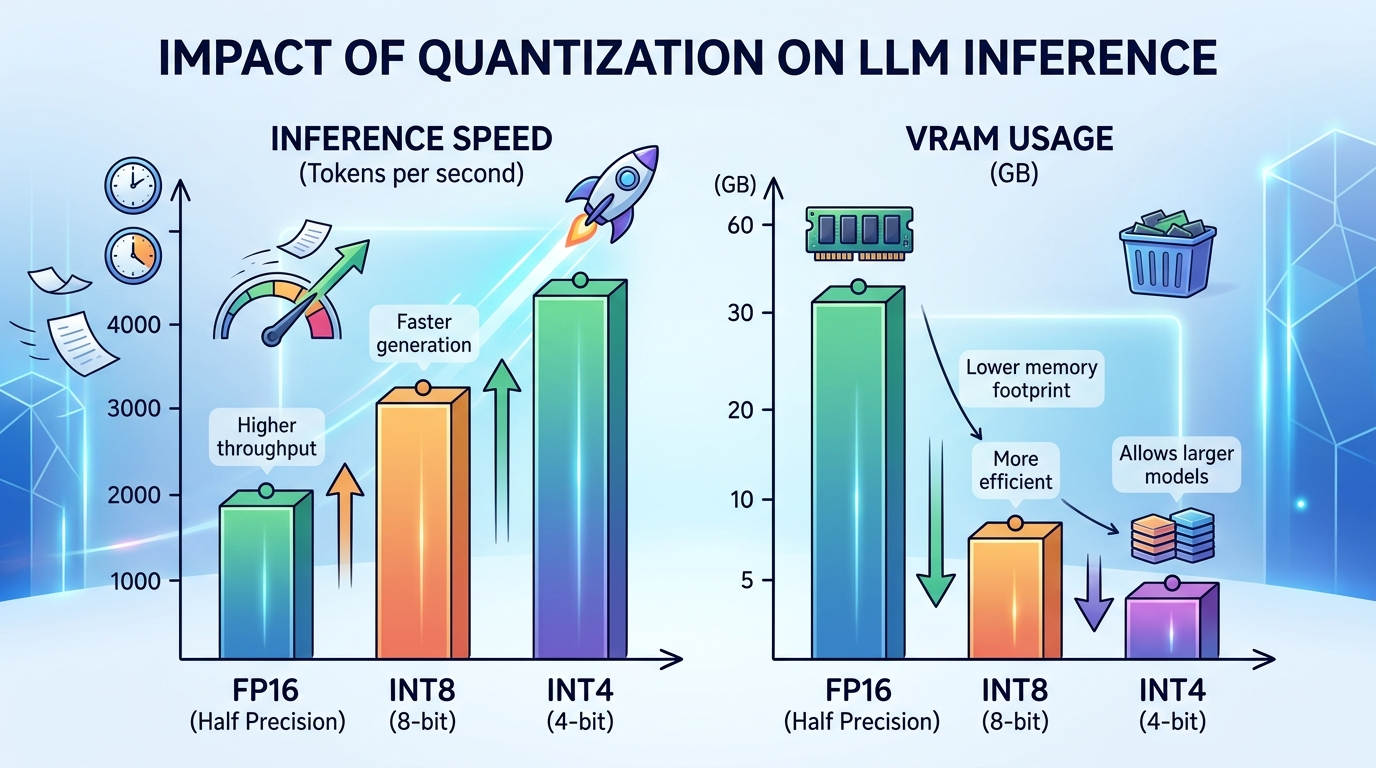
Graph illustrating the quantization impact on speed and VRAM usage

When configuring local large language models, performance depends on three core parameters: total parameter size, quantization level, and context window allocation. Tuning these settings determines wh

Categories local-ai Tags context-window, local-llm, model-size, performance, quantization Leave a comment

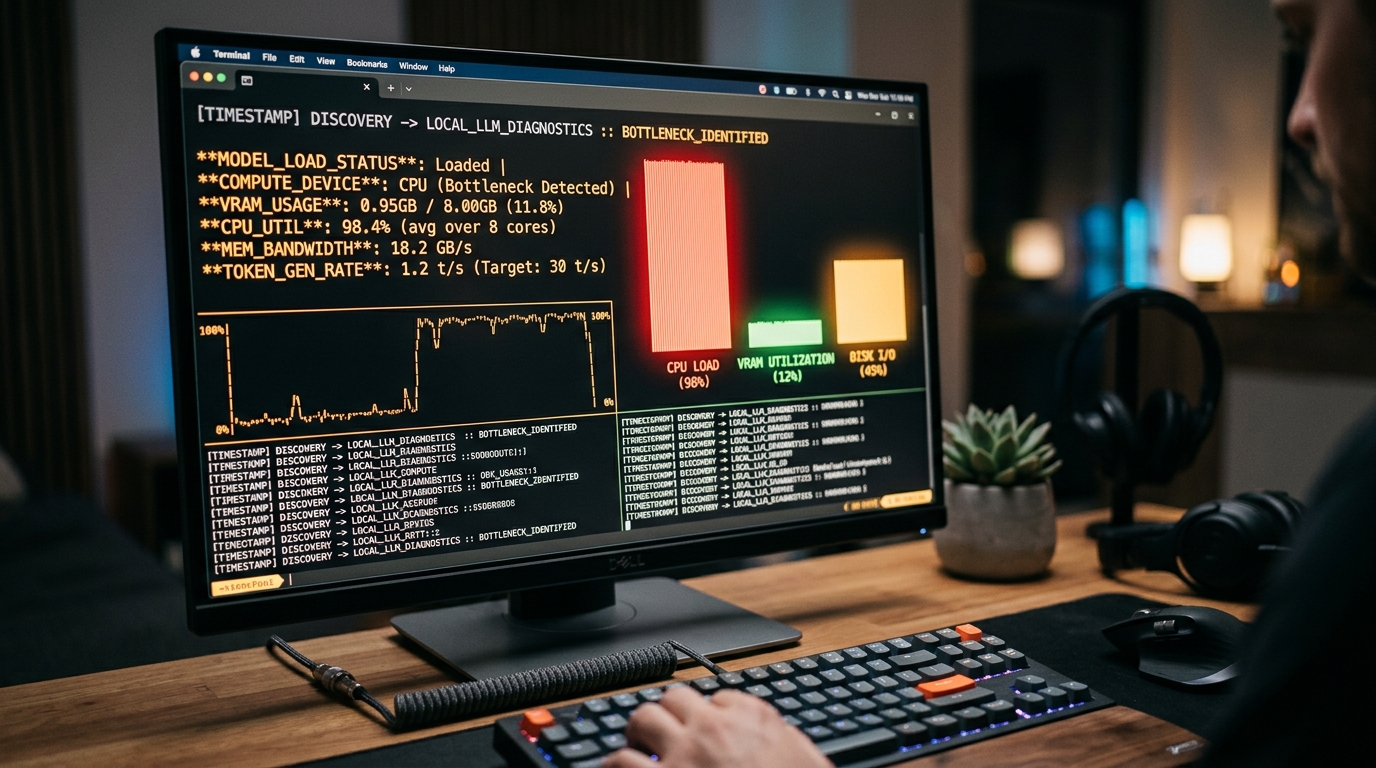
Diagnosing a Local LLM Hardware Bottleneck: CPU Fallback and GPU Issues

September 20, 2026 by REIBuys Engineering Team
A command line interface showing performance metrics and warnings indicating a hardware bottleneck in a local LLM setup.

Understanding why your graphics hardware remains idle or why your system reverts to slow processing modes is the first step toward reclaiming high-speed local AI performance.

Categories local-ai Tags cpu-fallback, gpu, hardware, local-llm, monitoring Leave a comment

How to Make Local LLM Faster: The Ultimate Optimization Guide

September 20, 2026 by REIBuys Engineering Team
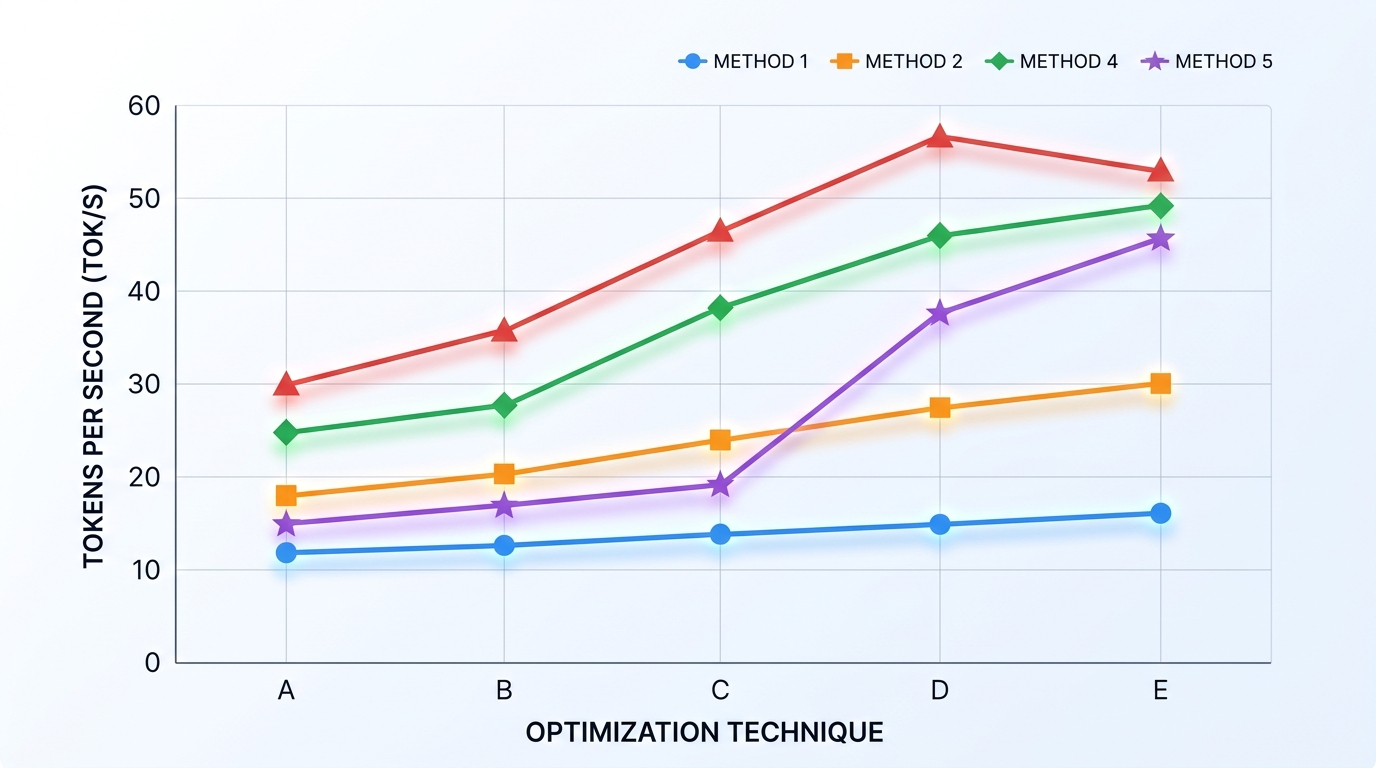
Chart showing how various optimization techniques improve local LLM tokens per second performance.

[IMAGE: Chart comparing tokens per second to show how to make local LLM faster]

Categories local-ai Tags inference-speed, local-llm, optimization, quantization, tokens-per-second Leave a comment

Local LLM Running Slow? A Complete Troubleshooting Guide

September 20, 2026 by REIBuys Engineering Team
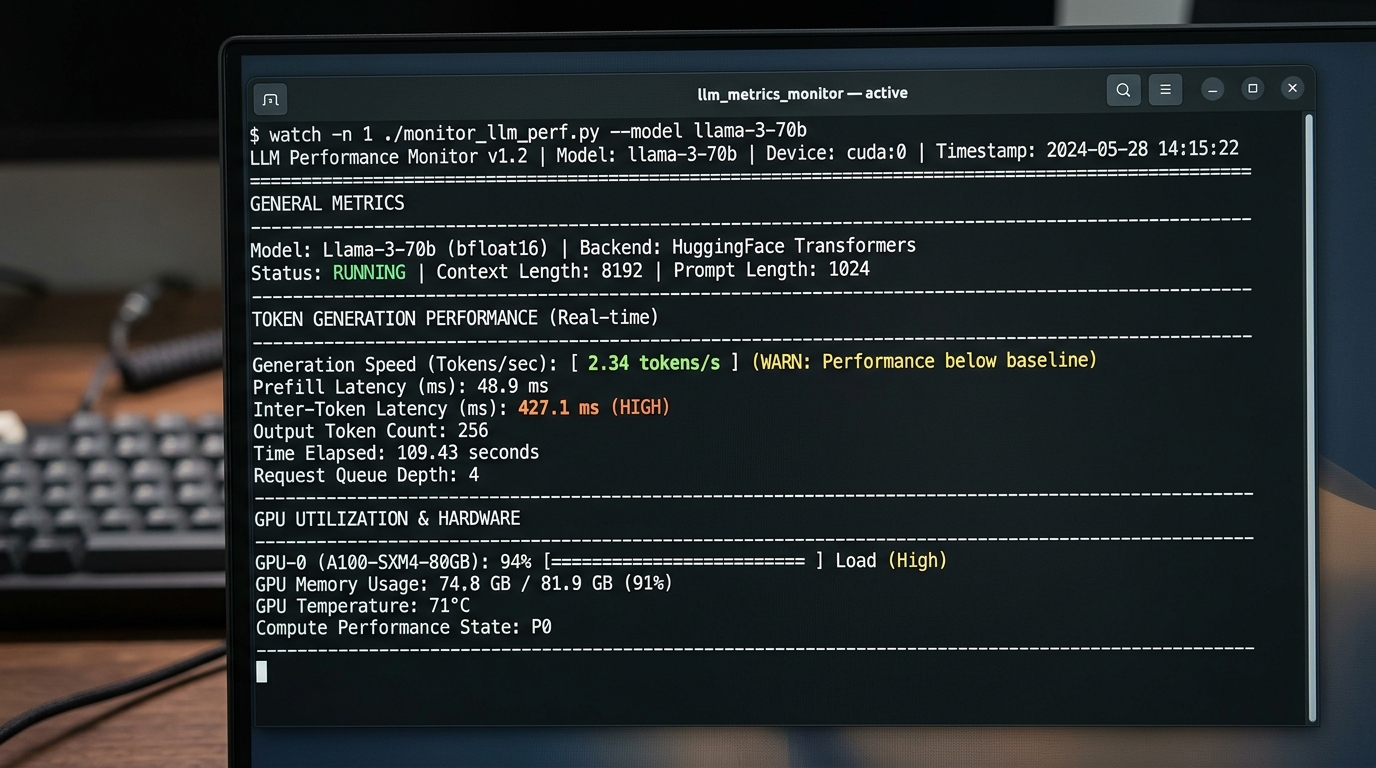
Terminal output displaying slow token generation speed metrics for a local large language model.

If you are experiencing severe performance degradation or high latency with local AI models, this comprehensive troubleshooting guide will help you isolate the root cause, verify system utilization, a

Categories local-ai Tags gpu-acceleration, local-llm, performance-tuning, troubleshooting Leave a comment
Free Forever Try NORA today - NORA

NORA Documentation

  • NORA Documentation
    • Getting Started with NORA
    • Interface Overview
    • Node Types
    • Building Workflows
    • Running Workflows
    • AI Features
    • Tool Library
    • Settings & Configuration
    • Reference
    • Let’s Get Started Workflow
    • Google Drive Collaboration

HF AI Video Studio Docs

  • HF AI Video Studio Documentation
    • 01 — Introduction
    • 02 — Getting Started
    • 03 — Interface Overview
    • 04 — Video Editing
    • 05 — Audio Editing
    • 06 — Voice Studio
    • 07 — Animated Captions
    • 08 — AI Image Generation
    • 09 — AI Video Generation
    • 10 — Talking Head / Lip-Sync Video
    • 11 — AI Audio & Music Generation
    • 12 — Long-Form Video Pipeline
    • 13 — Job Queue
    • 14 — Settings Reference
    • 15 — Exporting
    • 16 — Common Workflows
    • 17 — Troubleshooting & FAQ

Recent Posts

  • How to Safely Share Desktop Workflows Across Teams on Google Drive or OneDrive
  • Adding Conditional Logic and Error Handling to Desktop Script Automation
  • Stop Copy-Pasting: How Visual AI Agent Workflow Automation Simplifies Local File Sorting and Decisions
  • Local LLM vs ChatGPT Accuracy: Comparing Quality and Performance
  • Why Are Ollama Answers Bad? Troubleshooting LM Studio and Ollama
© 2026 Software - REIBuys • Built with GeneratePress