How to Force Local LLM to Use GPU Acceleration
Whether you rely on Ollama, LM Studio, Jan.ai, or llama.cpp, local AI frameworks sometimes fail to auto-detect hardware or default conservatively to CPU mode.

Whether you rely on Ollama, LM Studio, Jan.ai, or llama.cpp, local AI frameworks sometimes fail to auto-detect hardware or default conservatively to CPU mode.
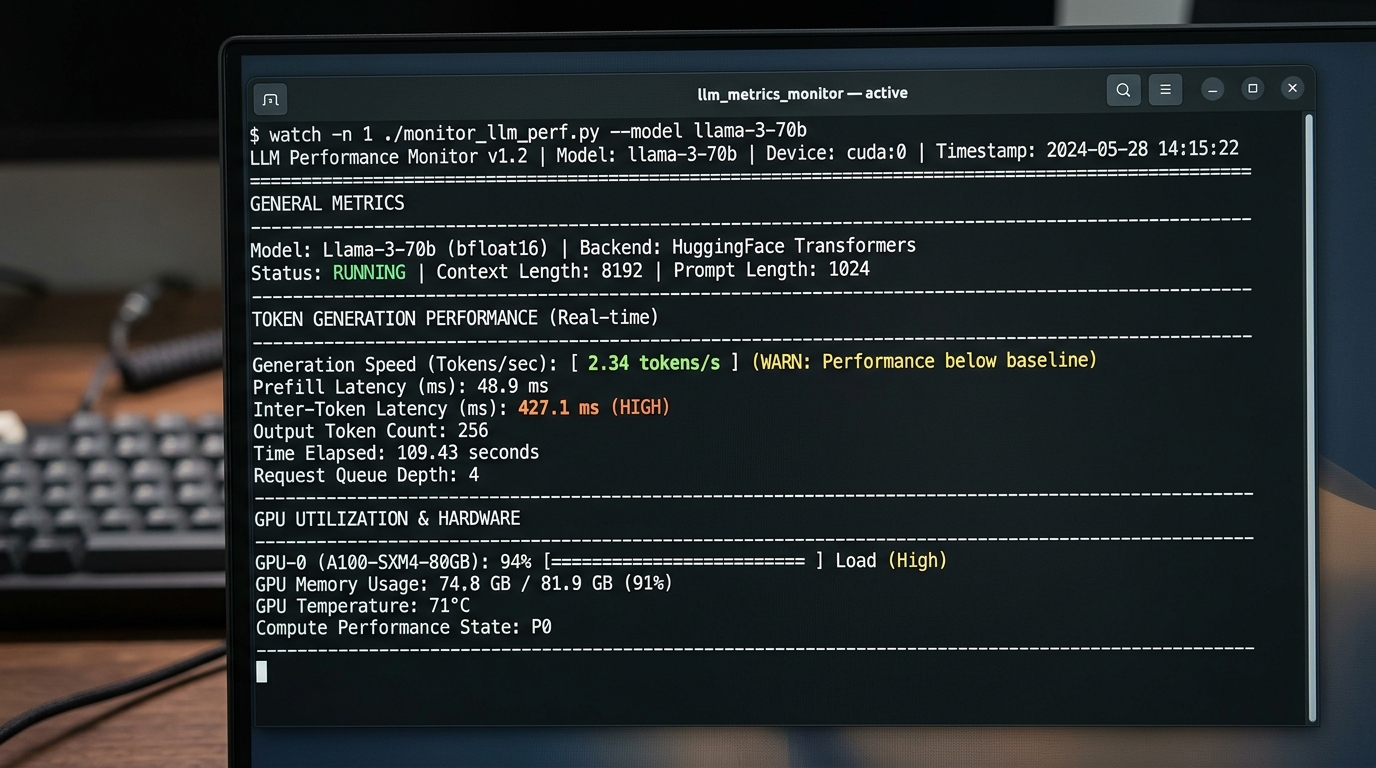
If you are experiencing severe performance degradation or high latency with local AI models, this comprehensive troubleshooting guide will help you isolate the root cause, verify system utilization, a