Managing Ollama Chat History & Making LM Studio Remember Chat
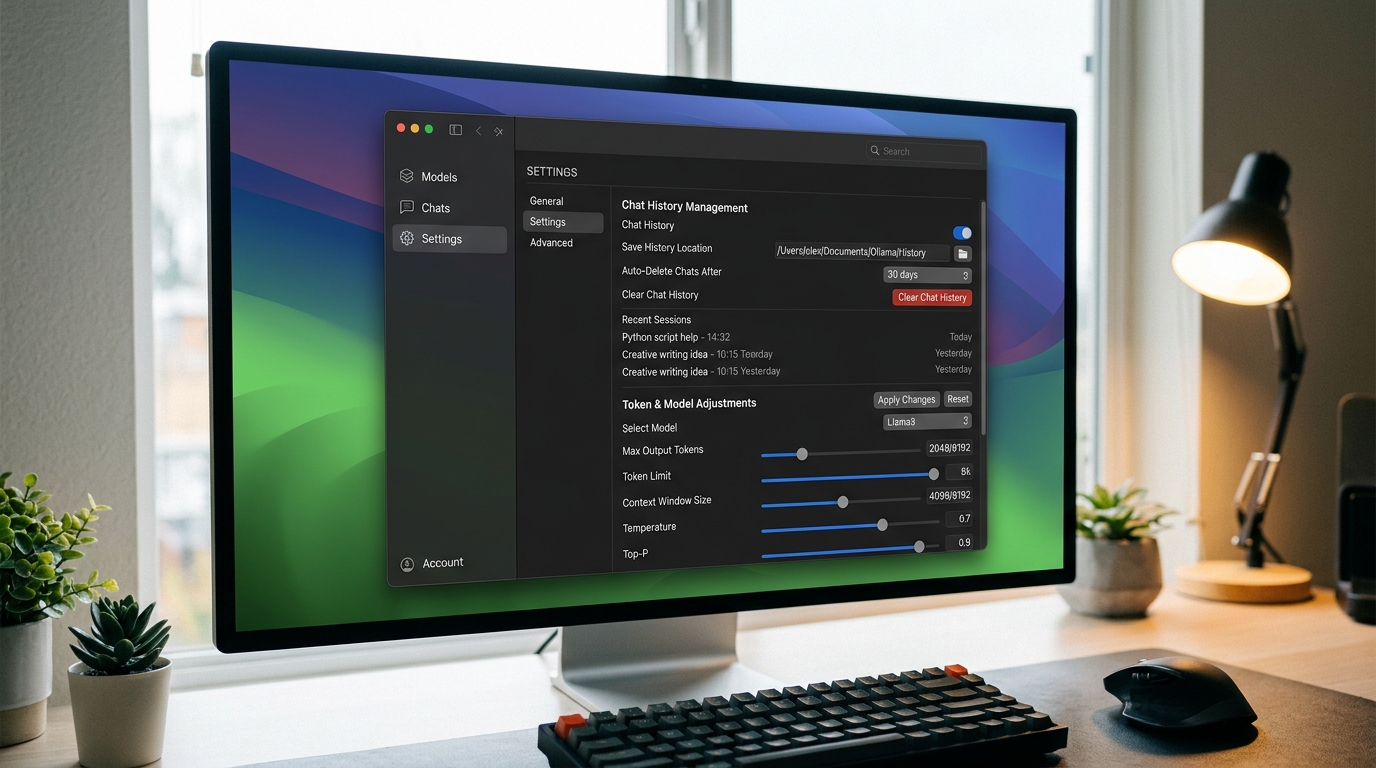
Before jumping into settings, it helps to clear up a common misconception about local model runners.
Before jumping into settings, it helps to clear up a common misconception about local model runners.
Running artificial intelligence models locally on desktop hardware has transitioned from a niche technical experiment into a mainstream operational strategy in 2026. Developers, privacy-conscious prof
Running artificial intelligence locally on macOS has evolved from an experimental tech hobby into an accessible daily workflow. In 2026, Mac users enjoy access to powerful open-source language models
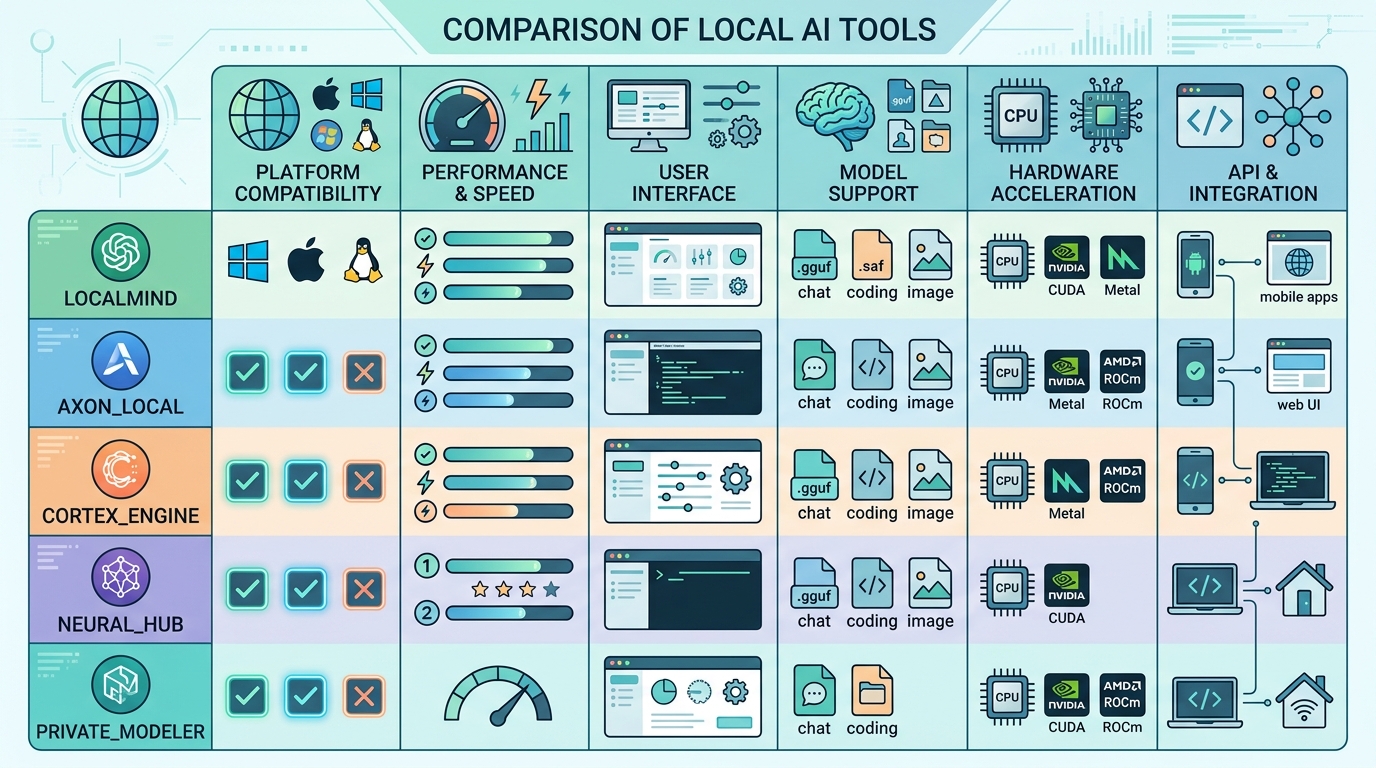
Ollama has established itself as one of the most widely used tools for running local language models. Its command-line interface, streamlined model registry, and background service architecture make i
When a local LLM runner fails to access hardware acceleration, it gracefully degrades by falling back to system memory and central processing unit cores. While this automatic fallback prevents applica
Whether you rely on Ollama, LM Studio, Jan.ai, or llama.cpp, local AI frameworks sometimes fail to auto-detect hardware or default conservatively to CPU mode.

[IMAGE: Split screen showing Ollama CLI interface and LM Studio GUI for comparison]