Context Window Strategies for Local LLMs: Best Practices & RAG Integration
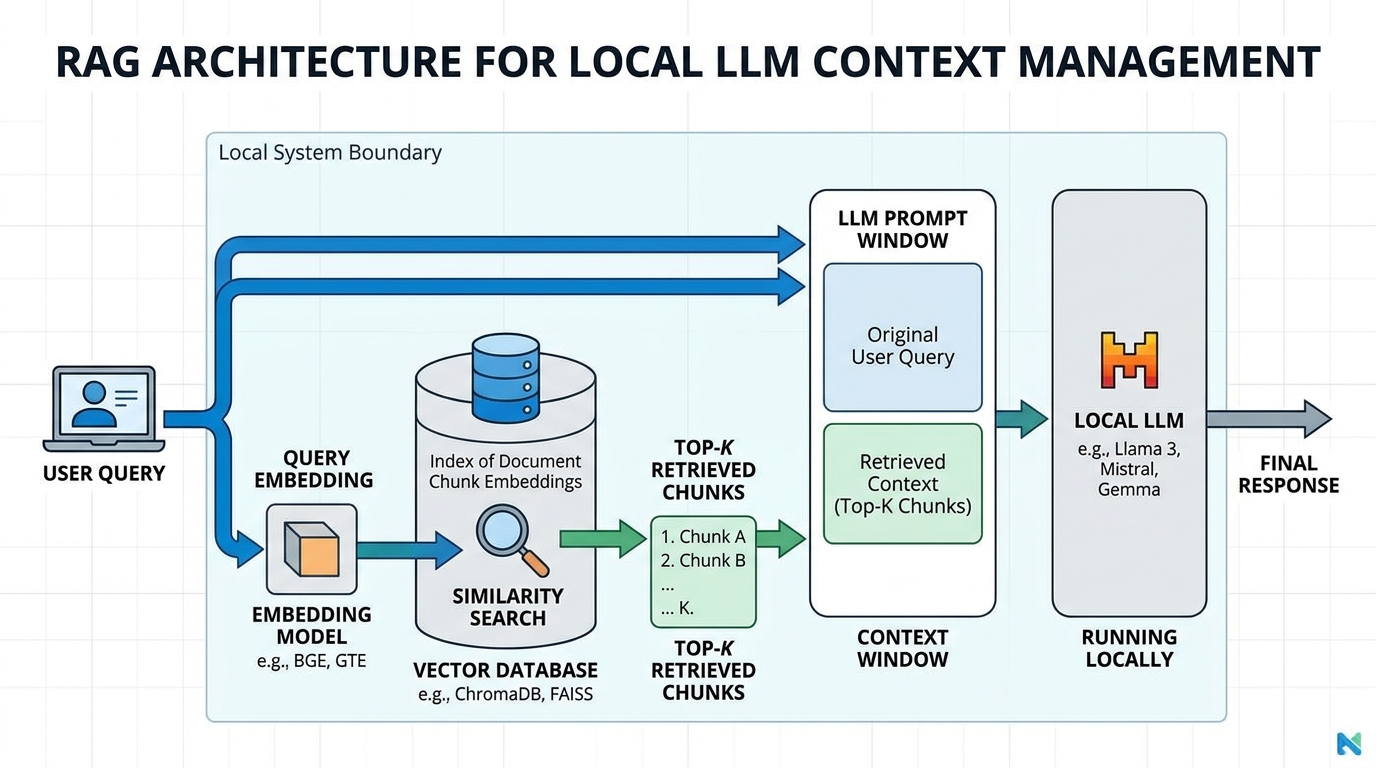
Without active memory management, local LLMs quickly hit processing bottlenecks, experience performance degradation, or throw runtime out-of-memory errors.
Without active memory management, local LLMs quickly hit processing bottlenecks, experience performance degradation, or throw runtime out-of-memory errors.
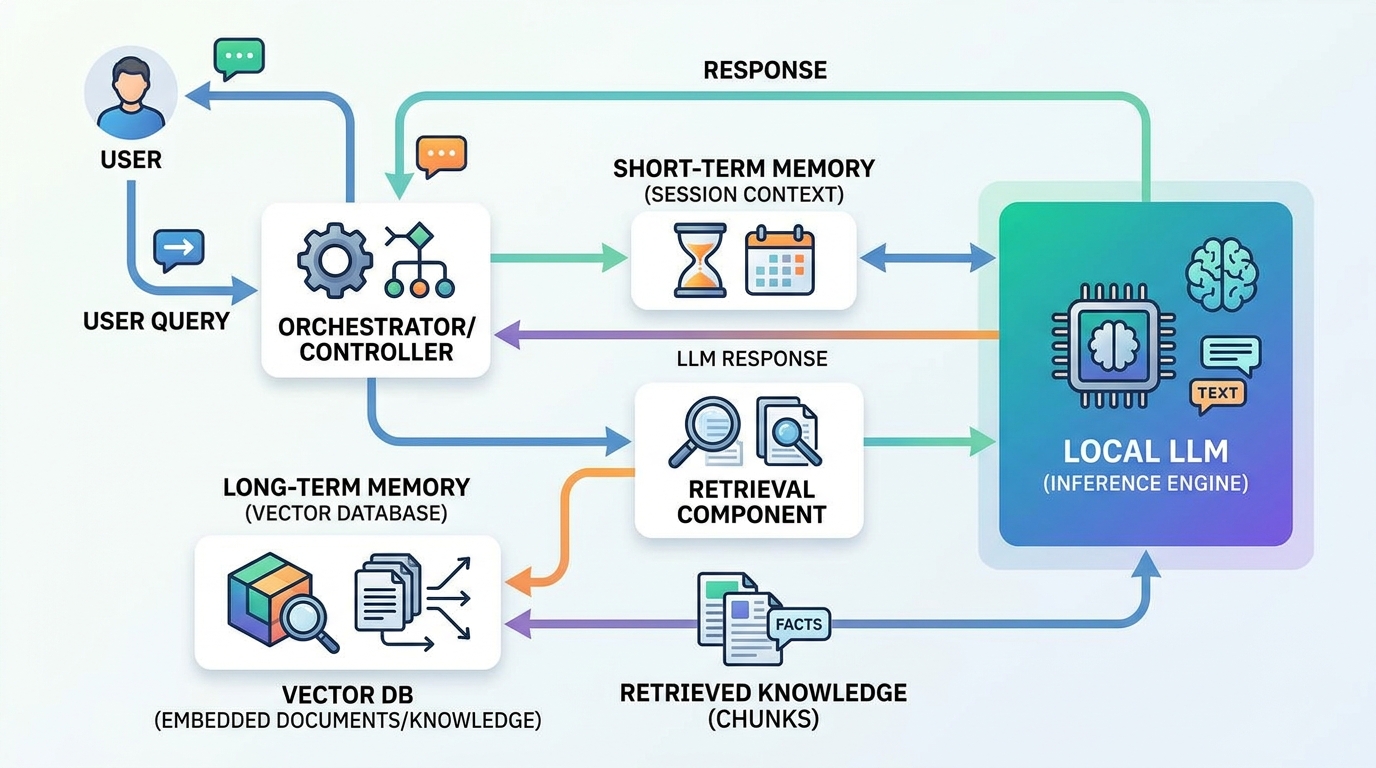
As local open-weight models rival proprietary cloud APIs in reasoning performance, developers and system architects are deploying them for sensitive data operations, technical assistant roles, and aut
Standard language model implementations often struggle when tasked with answering questions about proprietary enterprise data. Standard base models lack knowledge of your company’s internal documentat
Building high-performance, developer-friendly local Retrieval-Augmented Generation (RAG) applications requires picking a robust, modular software architecture. While running local model weights direct
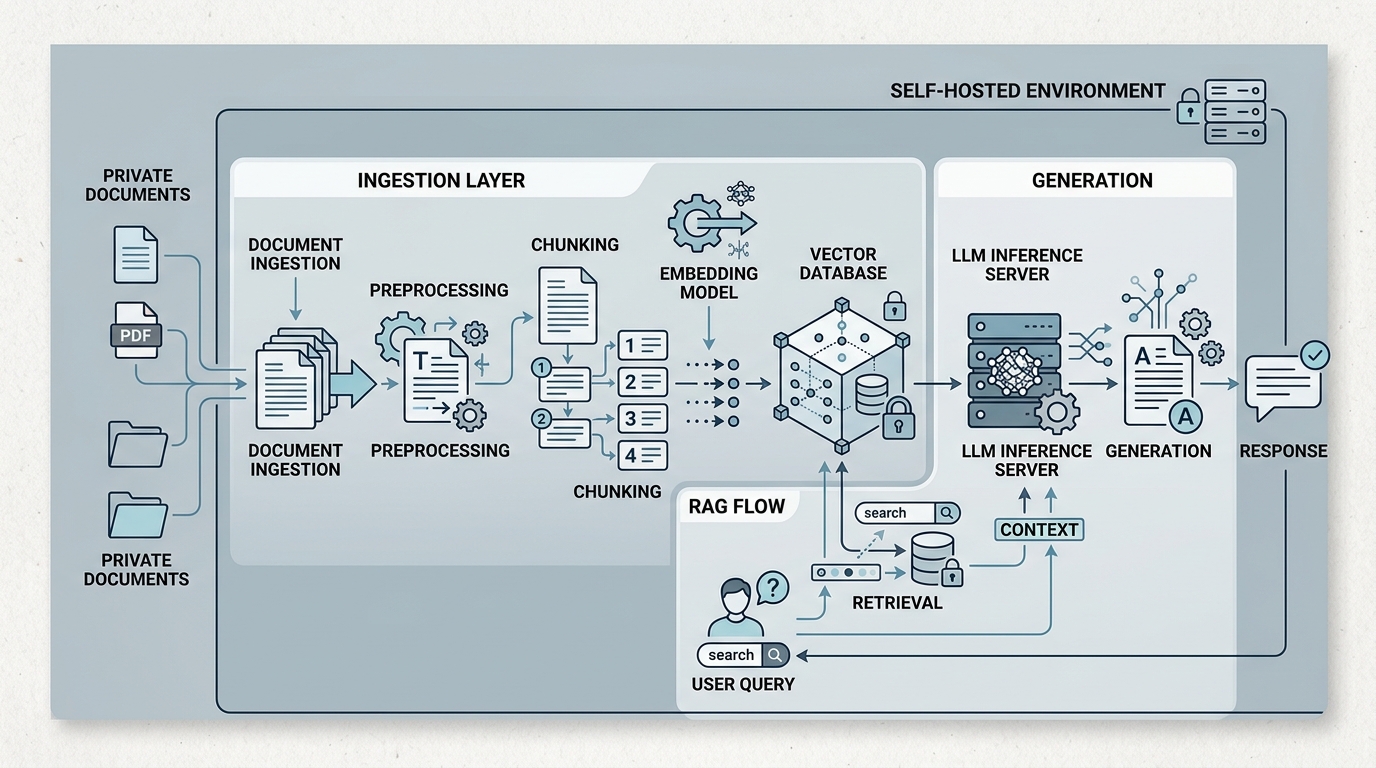
[IMAGE: Architecture diagram of a self-hosted RAG system for private documents]