Skip to content
Software – REIBuys
  • Home
    • More Apps
      • NORA Desktop App
        • NORA Documentation
        • NORA (EULA)
      • HF AI Video Studio
        • HF AI Video Studio Documentation
    • Blog
    • Support

rag

Context Window Strategies for Local LLMs: Best Practices & RAG Integration
October 8, 2026 by REIBuys Engineering Team
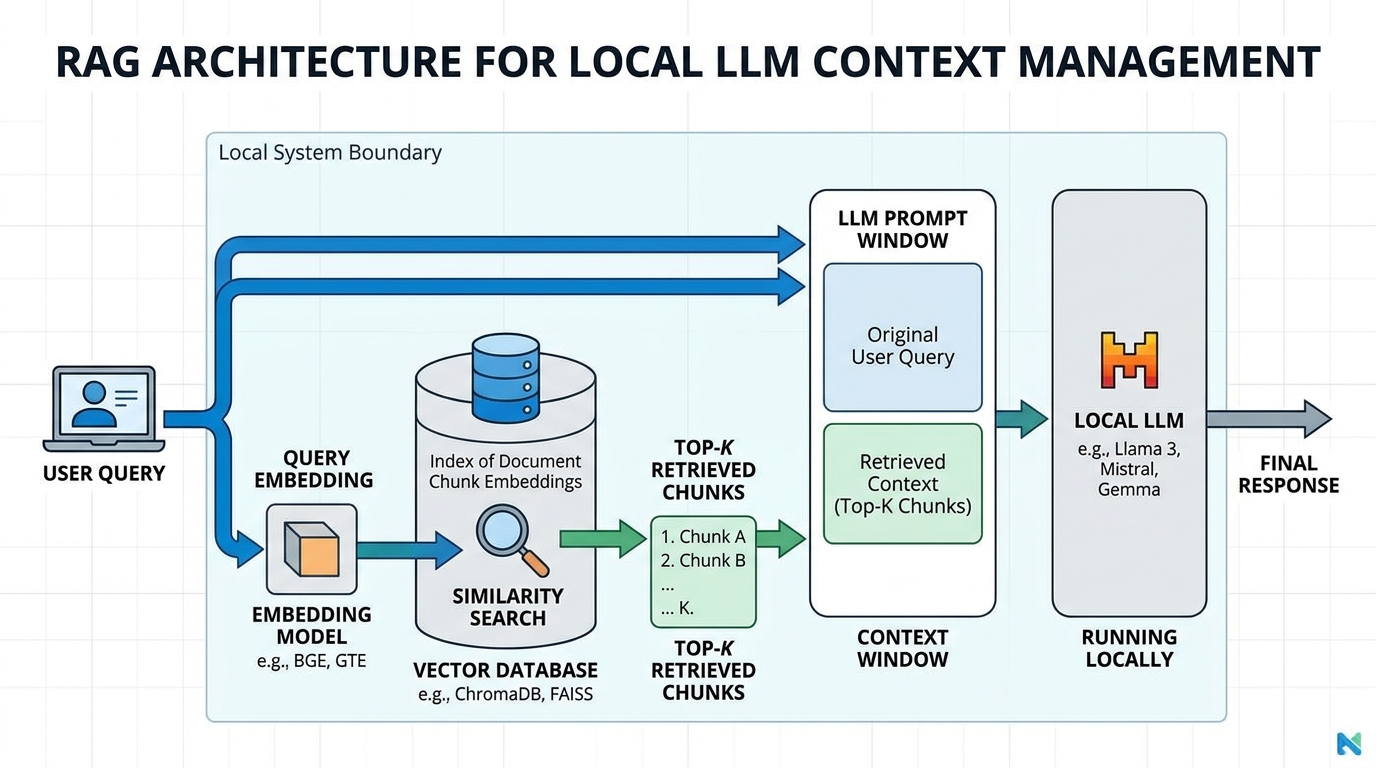
Architectural diagram illustrating Retrieval-Augmented Generation (RAG) for local LLM context management, showing the flow from user query to embedding model, vector database, and LLM prompt window.

Without active memory management, local LLMs quickly hit processing bottlenecks, experience performance degradation, or throw runtime out-of-memory errors.
Categories ai-coding-tools Tags context-management, local-llm, prompt-engineering, rag, vector-database Leave a comment

How to Add Memory to Your Local LLM (So It Stops Forgetting)

October 8, 2026 by REIBuys Engineering Team
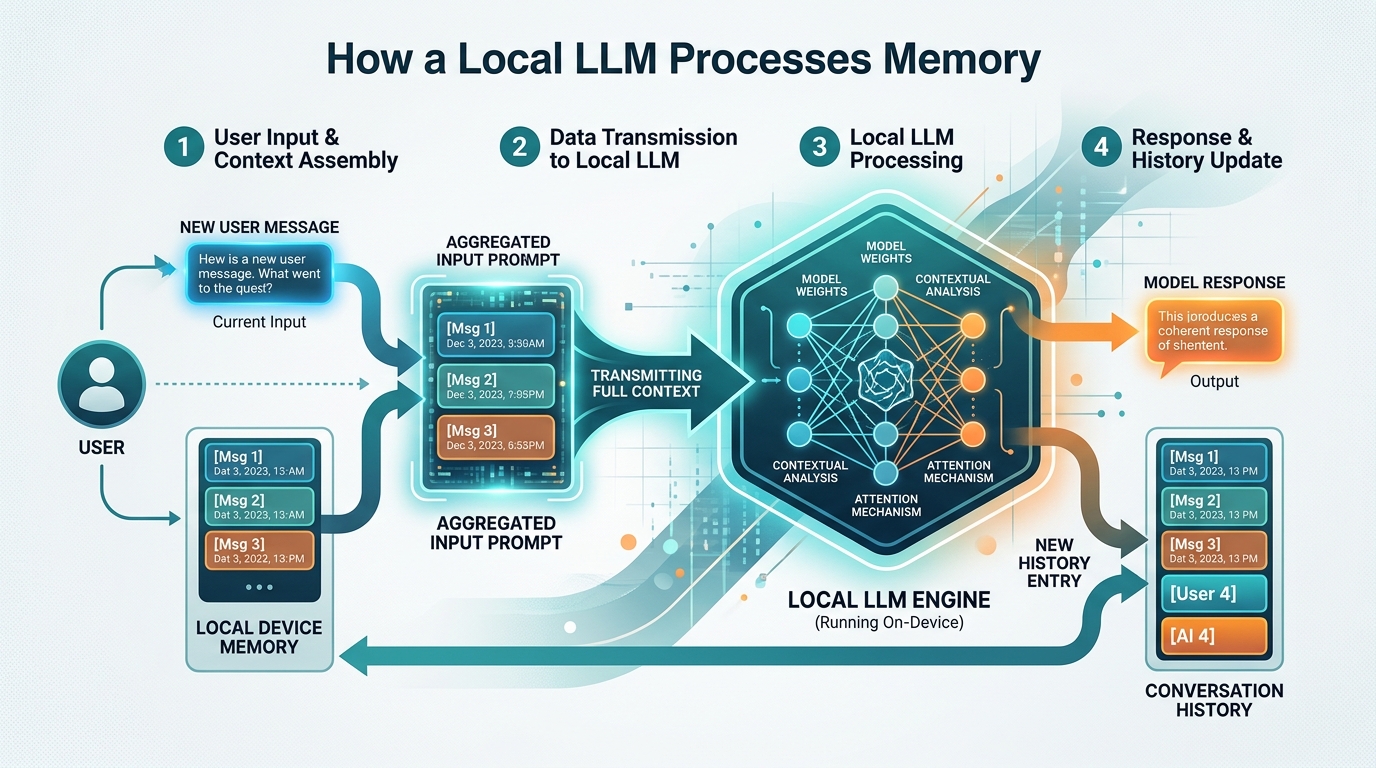
Diagram illustrating how a local LLM can remember previous messages by re-sending the entire chat history with each new prompt.

To fix memory loss in local AI systems, you first need to understand the fundamental architecture of neural language models.
Categories ai-coding-tools Tags context-window, llm-memory, local-llm, ollama, rag Leave a comment

Implementing RAG for Local LLM Memory and Context Management

October 8, 2026 by REIBuys Engineering Team
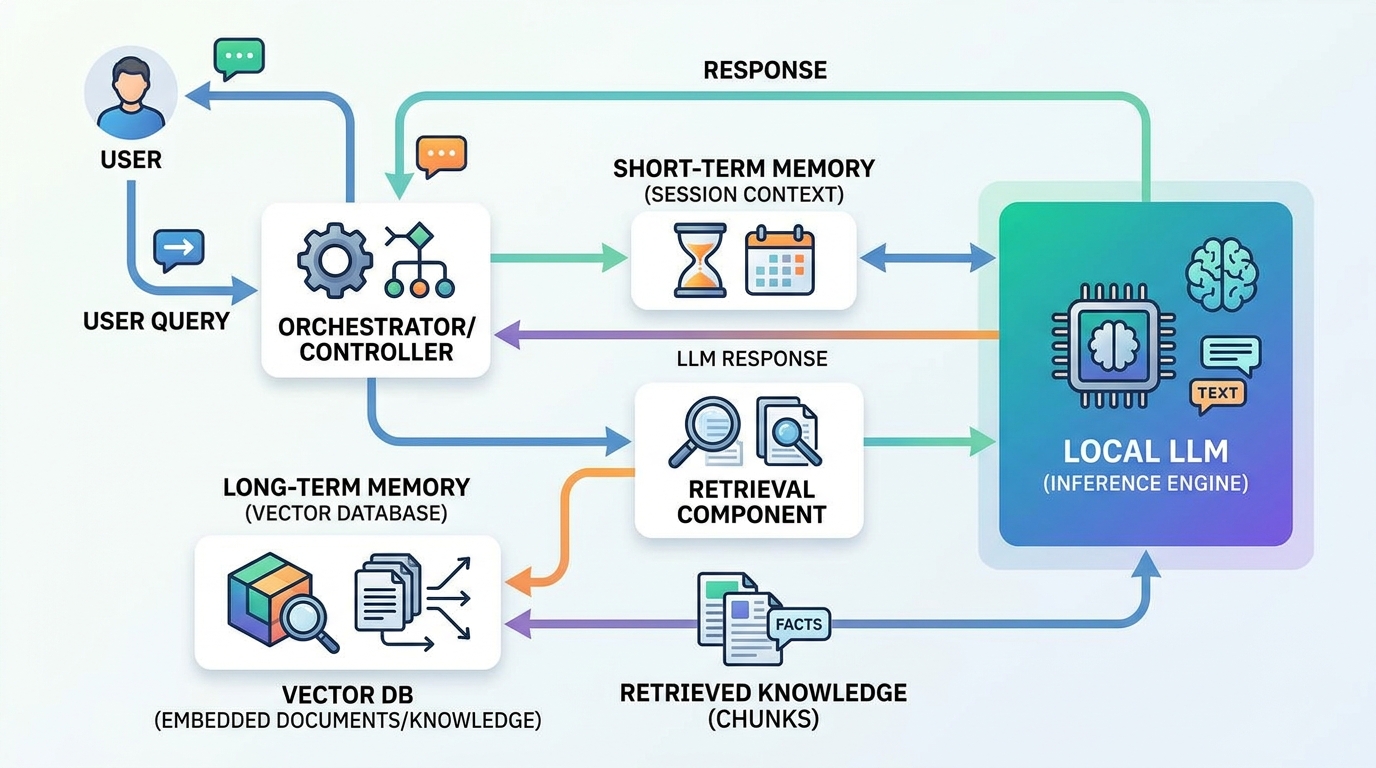
Architecture diagram showing the RAG process for local LLM memory, detailing how a user query triggers retrieval from a vector database before being fed into a local LLM for response generation.

As local open-weight models rival proprietary cloud APIs in reasoning performance, developers and system architects are deploying them for sensitive data operations, technical assistant roles, and aut

Categories ai-coding-tools Tags chromadb, context-management, local-llm, rag, vector-database Leave a comment

Tokenmaxxing vs RAG Tradeoffs: Optimizing AI Context

August 30, 2026 by REIBuys Engineering Team

As context windows expand across modern Large Language Models (LLMs)—with standard models accepting 200,000 tokens and specialized models supporting over 1,000,000 tokens—ai architects face a major de

Categories ai-coding-tools Tags ai-architecture, context-window, rag, tokenmaxxing, vector-search Leave a comment
Free Forever Try NORA today - NORA

NORA Documentation

  • NORA Documentation
    • Getting Started with NORA
    • Interface Overview
    • Node Types
    • Building Workflows
    • Running Workflows
    • AI Features
    • Tool Library
    • Settings & Configuration
    • Reference
    • Let’s Get Started Workflow
    • Google Drive Collaboration

HF AI Video Studio Docs

  • HF AI Video Studio Documentation
    • 01 — Introduction
    • 02 — Getting Started
    • 03 — Interface Overview
    • 04 — Video Editing
    • 05 — Audio Editing
    • 06 — Voice Studio
    • 07 — Animated Captions
    • 08 — AI Image Generation
    • 09 — AI Video Generation
    • 10 — Talking Head / Lip-Sync Video
    • 11 — AI Audio & Music Generation
    • 12 — Long-Form Video Pipeline
    • 13 — Job Queue
    • 14 — Settings Reference
    • 15 — Exporting
    • 16 — Common Workflows
    • 17 — Troubleshooting & FAQ

Recent Posts

  • How to Safely Share Desktop Workflows Across Teams on Google Drive or OneDrive
  • Adding Conditional Logic and Error Handling to Desktop Script Automation
  • Stop Copy-Pasting: How Visual AI Agent Workflow Automation Simplifies Local File Sorting and Decisions
  • Local LLM vs ChatGPT Accuracy: Comparing Quality and Performance
  • Why Are Ollama Answers Bad? Troubleshooting LM Studio and Ollama
© 2026 Software - REIBuys • Built with GeneratePress