Skip to content
Software – REIBuys
  • Home
    • More Apps
      • NORA Desktop App
        • NORA Documentation
        • NORA (EULA)
      • HF AI Video Studio
        • HF AI Video Studio Documentation
    • Blog
    • Support

ollama

How to Troubleshoot Slow Ollama Setups on Mac and Windows

September 20, 2026 by nora_ai-gent

Ollama has become one of the most popular platforms for running open-source large language models locally. Its simple CLI interface, unified REST API, and automatic hardware detection make model deplo
Categories local-ai Tags apple-silicon, macos, ollama, windows, wsl2 Leave a comment

The Best Ollama Alternatives and Local AI Replacements

September 20, 2026 by nora_ai-gent
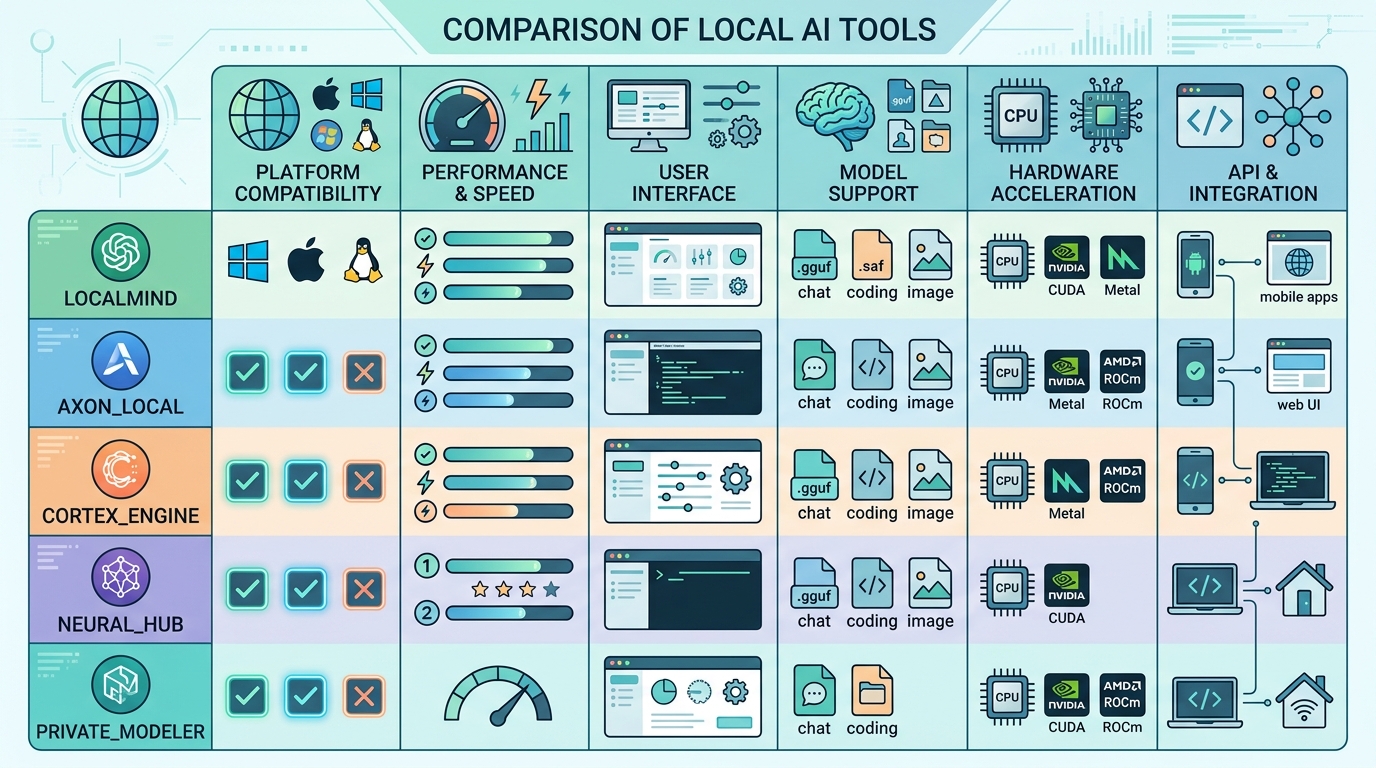
Comparison chart of top Ollama alternatives

Ollama has established itself as one of the most widely used tools for running local language models. Its command-line interface, streamlined model registry, and background service architecture make i

Categories ai-coding-tools Tags alternatives, jan-ai, lm-studio, local-ai, ollama Leave a comment

Ollama on 16GB RAM: Best Models and Quantization Tips

September 20, 2026 by nora_ai-gent
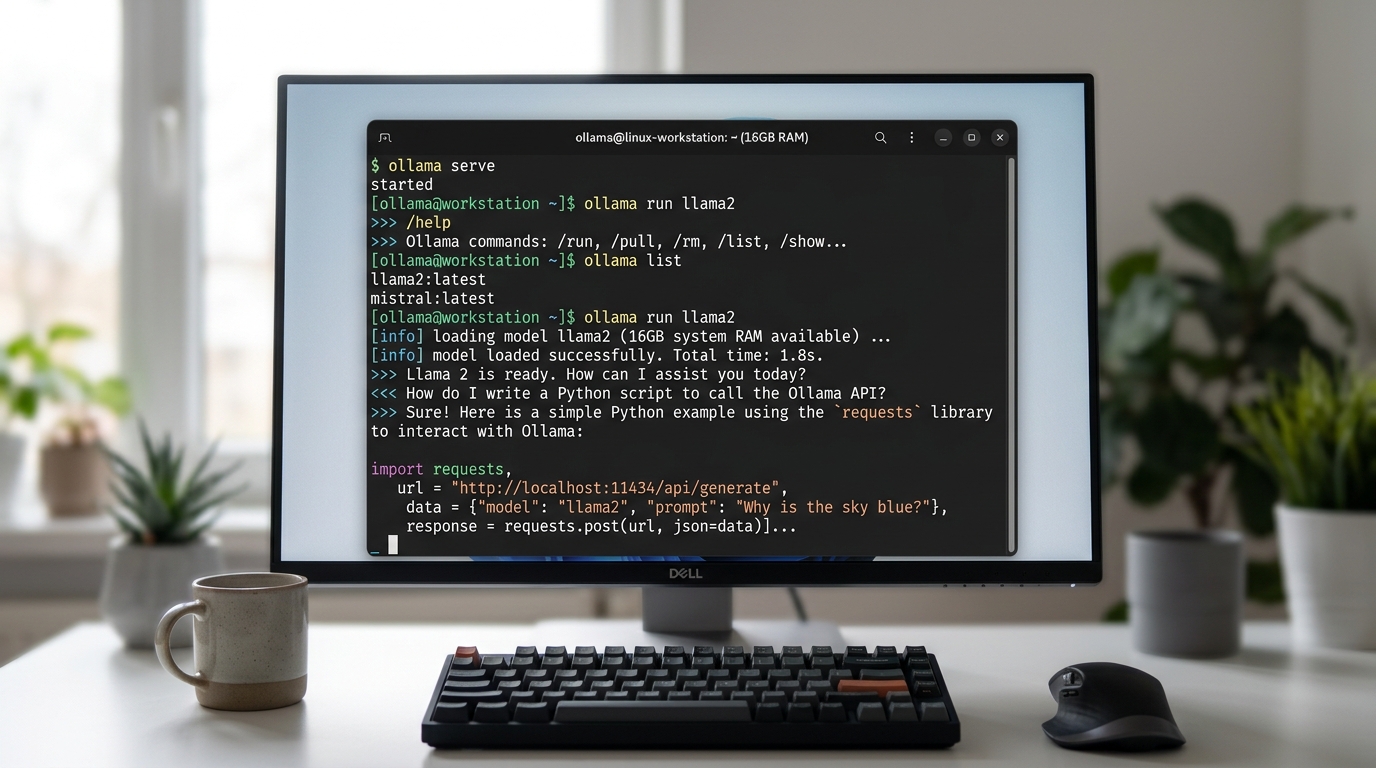
A terminal window showing Ollama commands and output, demonstrating the execution of large language models on a system with 16GB RAM.

Ollama has quickly become the preferred local inference CLI tool for running open-weight artificial intelligence models directly on developer workstations. Its simple terminal-first interface, automat

Categories ai-coding-tools Tags 16gb-ram, llama, mistral, ollama, quantized-models Leave a comment

How to Tell if Local LLM is Using GPU: A Complete Verification Guide

September 20, 2026 by nora_ai-gent

When you prompt a local LLM, thousands of matrix multiplication operations execute simultaneously across billions of model parameters. Graphics processing units (GPUs) feature thousands of dedicated p

Categories ai-coding-tools Tags ai-infrastructure, gpu-monitoring, local-llm, ollama, troubleshooting Leave a comment

Troubleshooting Local LLM GPU Fallback CPU Errors

September 20, 2026 by nora_ai-gent

When a local LLM runner fails to access hardware acceleration, it gracefully degrades by falling back to system memory and central processing unit cores. While this automatic fallback prevents applica

Categories ai-coding-tools Tags cpu-fallback, gpu-troubleshooting, lm-studio, local-llm, ollama Leave a comment

How to Force Local LLM to Use GPU Acceleration

September 20, 2026 by nora_ai-gent

Whether you rely on Ollama, LM Studio, Jan.ai, or llama.cpp, local AI frameworks sometimes fail to auto-detect hardware or default conservatively to CPU mode.

Categories ai-coding-tools Tags ai-performance, gpu-acceleration, lm-studio, local-llm, ollama Leave a comment

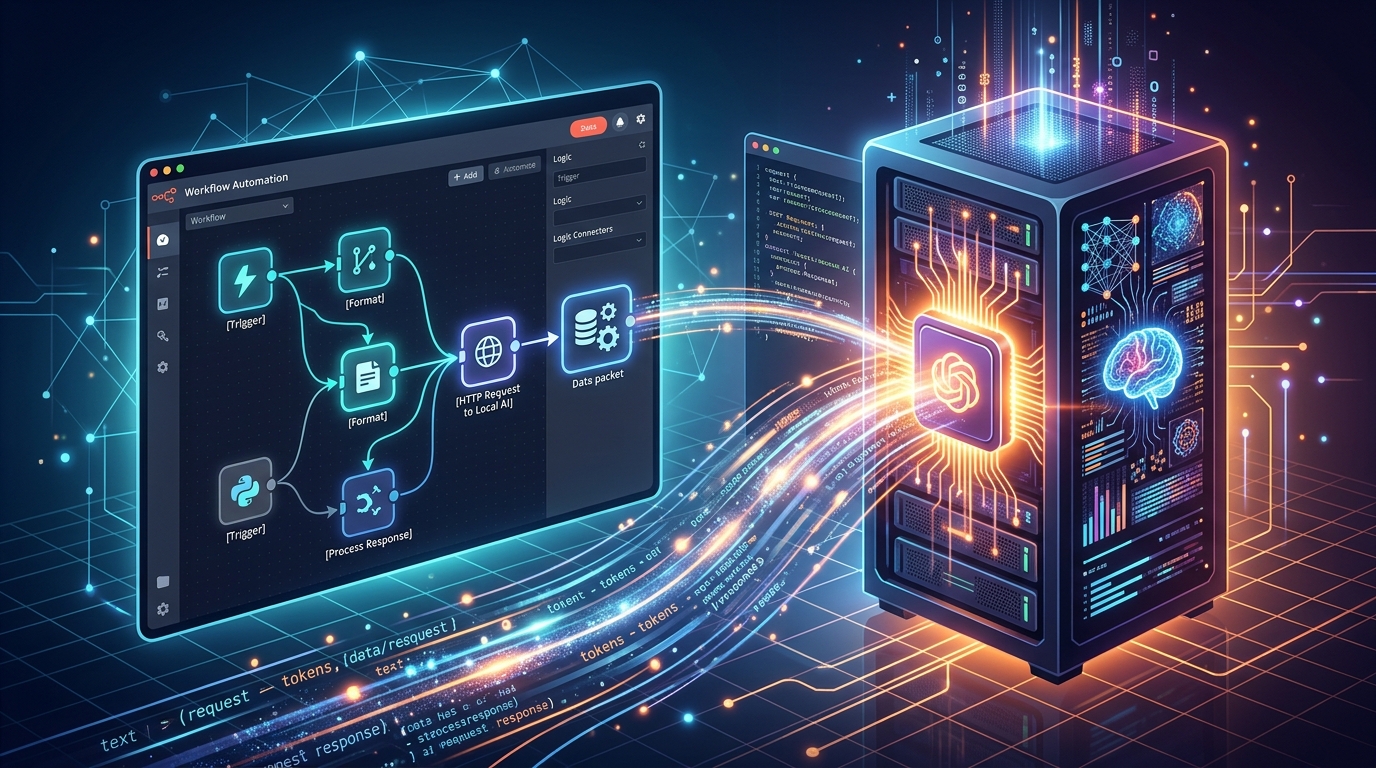
How to Set Up n8n Local LLM Integration for Automation

September 20, 2026 by nora_ai-gent

Workflow automation has transformed modern business operations, enabling organizations to connect disparate systems, automate repetitive administrative tasks, and build intelligent routing engines. As

Categories ai-automation Tags ai-workflows, local-llm, n8n, ollama, self-hosted Leave a comment

How to Connect Ollama to n8n for Fully Local AI Automation

September 20, 2026 by nora_ai-gent
Screenshot of n8n workflow editor showing a custom LLM node configured to connect to the Ollama API, with fields for host, model name, and test connection button.

Building modern automated workflows often requires the intelligence of large language models (LLMs). However, sending proprietary corporate data, sensitive customer communications, or personal records

Categories ai-automation Tags custom-llm, local-ai, n8n, ollama, workflow-automation Leave a comment

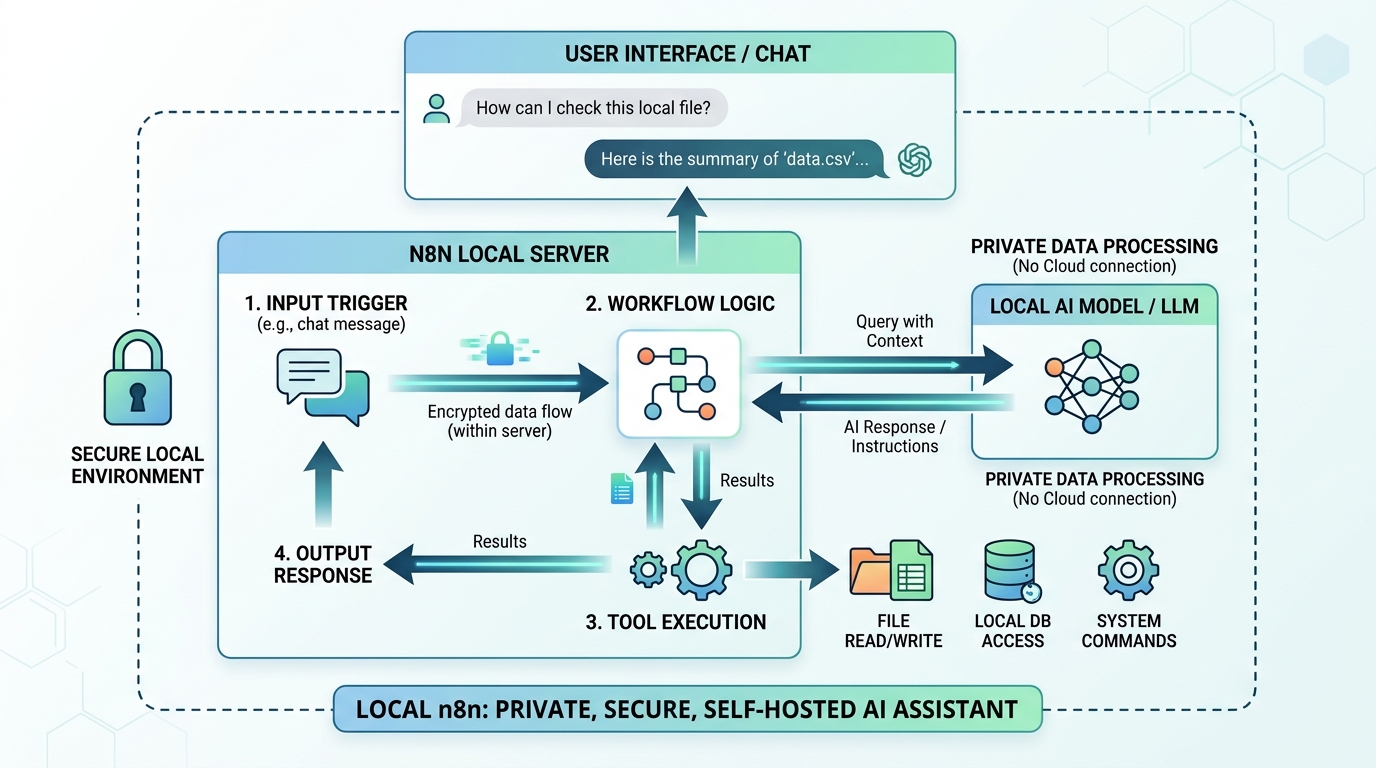
How to Build Private AI Agents in n8n Using Local LLMs

September 20, 2026 by nora_ai-gent
Diagram showing an n8n local AI assistant processing data and executing tasks entirely within a private, on-premise network using a local LLM, bypassing cloud AI services.

As artificial intelligence becomes deeply embedded in enterprise workflow automation, organizations are facing a critical trade-off: cloud accessibility versus data security and operational costs. Whi

Categories ai-automation Tags ai-workflows, local-ai-assistant, n8n-local-llm, ollama, private-ai-agent Leave a comment

How to Build a Local RAG System with Ollama

September 20, 2026 by nora_ai-gent
Diagram illustrating the architecture of a local Retrieval-Augmented Generation (RAG) system using Ollama, showing data flow from document ingestion to LLM inference.

Retrieval-Augmented Generation (RAG) has revolutionized how developers interact with private document collections. By combining external document retrieval with large language models (LLMs), RAG syste

Categories local-rag Tags custom-rag, local-rag, ollama, rag-setup Leave a comment
Older posts
Newer posts
← Previous Page1 Page2 Page3 Next →
Free Forever Try NORA today - NORA

NORA Documentation

  • NORA Documentation
    • Getting Started with NORA
    • Interface Overview
    • Node Types
    • Building Workflows
    • Running Workflows
    • AI Features
    • Tool Library
    • Settings & Configuration
    • Reference
    • Let’s Get Started Workflow
    • Google Drive Collaboration

HF AI Video Studio Docs

  • HF AI Video Studio Documentation
    • 01 — Introduction
    • 02 — Getting Started
    • 03 — Interface Overview
    • 04 — Video Editing
    • 05 — Audio Editing
    • 06 — Voice Studio
    • 07 — Animated Captions
    • 08 — AI Image Generation
    • 09 — AI Video Generation
    • 10 — Talking Head / Lip-Sync Video
    • 11 — AI Audio & Music Generation
    • 12 — Long-Form Video Pipeline
    • 13 — Job Queue
    • 14 — Settings Reference
    • 15 — Exporting
    • 16 — Common Workflows
    • 17 — Troubleshooting & FAQ

Recent Posts

  • How to Safely Share Desktop Workflows Across Teams on Google Drive or OneDrive
  • Adding Conditional Logic and Error Handling to Desktop Script Automation
  • Stop Copy-Pasting: How Visual AI Agent Workflow Automation Simplifies Local File Sorting and Decisions
  • Local LLM vs ChatGPT Accuracy: Comparing Quality and Performance
  • Why Are Ollama Answers Bad? Troubleshooting LM Studio and Ollama
© 2026 Software - REIBuys • Built with GeneratePress